Here, AI infra options means ways to get compute for AI work: GPU clouds you rent by the hour and systems you buy for your own site. Lambda Cloud ranks first because its page publishes per-GPU-hour prices from $0.69 to $7.99 plus HGX B200 and H100 cluster prices. CoreWeave Cloud is #2 with on-demand and spot prices, and Oracle Cloud Infrastructure GPU Compute is #3 with NVIDIA and AMD GPUs.
Instance prices per GPU-hour start at $0.69 for an NVIDIA Quadro RTX 6000 and run to $7.99 for a single NVIDIA B200 SXM6; the page says these prices take effect November 16, 2026
Teams that want to rent NVIDIA B200 or H100 GPUs by the hour with every price on one page
Not published; the page directs visitors to Get DGX and a Talk to Us form
Enterprises building their own AI data center with NVIDIA support and certified storage partners
Pick by what you want
Best overall
Lambda Cloud
Best spot prices published
CoreWeave Cloud
Best for AMD GPUs
Oracle Cloud Infrastructure GPU Compute
Best desk-side system
NVIDIA DGX Station
Best small local system
NVIDIA DGX Spark
Best rack-scale AMD option
AMD Instinct MI400 Series
The ranking
1
Lambda Cloud
Answrs VerdictThe most complete published price list here, from single GPUs to 256-GPU clusters.
Price: Instance prices per GPU-hour start at $0.69 for an NVIDIA Quadro RTX 6000 and run to $7.99 for a single NVIDIA B200 SXM6; the page says these prices take effect November 16, 20261-Click Clusters: NVIDIA HGX B200 is $9.86 per GPU-hour on 16 GPUs, $9.36 on 64 and $8.87 on 256 or more; HGX H100 is $6.16, $5.85 and $5.54, for terms of 2 weeks to 1 yearInstance example: An NVIDIA HGX B200 instance has 180 GB of VRAM per GPU, 208 vCPUs and 2900 GiB of RAM at $7.69 per GPU-hour; HGX H100 is $4.59Product range: Its home page lists Superclusters on single-tenant NVIDIA GB300 NVL72, 1-Click Clusters on HGX B200 and H100, and instances that spin up in minutes
Lambda Cloud lists instance prices per GPU-hour from $0.69 for an NVIDIA Quadro RTX 6000 to $7.99 for a single NVIDIA B200 SXM6, and the page says the prices take effect November 16, 2026. 1-Click Clusters price HGX B200 at $9.86 per GPU-hour on 16 GPUs, $9.36 on 64 and $8.87 on 256 or more, and HGX H100 at $6.16, $5.85 and $5.54. An HGX B200 instance has 180 GB of VRAM per GPU, 208 vCPUs and 2900 GiB of RAM at $7.69 per GPU-hour. Clusters of a year or longer are listed only as "Talk to our team".
Go ifTeams that want to rent NVIDIA B200 or H100 GPUs by the hour with every price on one page
Skip ifYou need a price for 1-year-plus clusters, which the page lists only as "Talk to our team"
Why #1 over #2: It publishes more prices than CoreWeave, which lists GB300 NVL72 and HGX B300 as contact sales.
2
CoreWeave Cloud
Answrs VerdictPublishes on-demand and spot prices, but the newest systems are contact sales.
Price: On-demand is $68.80 per hour for an 8-GPU NVIDIA HGX B200 instance, $49.24 for HGX H100 and $50.44 for HGX H200; prices are per instance per hourRack-scale: NVIDIA GB200 NVL72 is $42.00 per hour for 4 GPUs; GB300 NVL72 and HGX B300 are "Contact sales"Spot: Spot is $34.11 per hour for HGX B200, $19.71 for HGX H100 and $20.93 for HGX H200Specs: HGX H200 has 141 GB of VRAM per GPU, 128 vCPUs and 2,048 GB of system RAM; HGX B200 has 180 GB of VRAM per GPU
CoreWeave lists on-demand prices of $68.80 per hour for an 8-GPU NVIDIA HGX B200 instance, $49.24 for HGX H100 and $50.44 for HGX H200, all per instance. NVIDIA GB200 NVL72 is $42.00 per hour for 4 GPUs, while GB300 NVL72 and HGX B300 are contact sales. Spot is $34.11 for HGX B200, $19.71 for HGX H100 and $20.93 for HGX H200. HGX H200 has 141 GB of VRAM per GPU, 128 vCPUs and 2,048 GB of system RAM.
Go ifTeams that want a full on-demand and spot price table for the newest NVIDIA systems
Skip ifYou need a published price for GB300 or HGX B300, which are listed as contact sales
Why #2 over #3: It publishes spot prices for several systems, while Oracle lists a single GPU price.
3
Oracle Cloud Infrastructure GPU Compute
Answrs VerdictOffers NVIDIA and AMD GPUs, but only one price is on the page.
Price: The page lists one price: AMD Instinct MI300X GPUs with 192 GB of memory at $6 per GPU-hour; no other GPU price is on the pageScale: An OCI Supercluster scales up to 131,072 NVIDIA Blackwell B200 GPUs, per the page footnoteNetwork: Up to 3,200 Gb/sec of RDMA cluster network bandwidth for bare metal instances with NVIDIA B200, H200 and H100 GPUs and AMD Instinct MI300X acceleratorsInstance types: GPUs are offered as bare metal instances, virtual machines and Kubernetes clusters, with NVIDIA and AMD GPUs
Oracle Cloud Infrastructure offers NVIDIA and AMD GPUs as bare metal instances, virtual machines and Kubernetes clusters. Its page lists one price, $6 per GPU-hour for AMD Instinct MI300X GPUs with 192 GB of memory. A Supercluster scales up to 131,072 NVIDIA Blackwell B200 GPUs per the page footnote, with up to 3,200 Gb/sec of RDMA cluster network bandwidth on bare metal instances.
Go ifTeams that want a choice of NVIDIA or AMD GPUs on bare metal or virtual machines
Skip ifYou need a price for NVIDIA GPUs from this page, which lists only the MI300X rate
Why #3 over #4: It publishes a GPU price and cluster scale, while Azure publishes no price on the pages we read.
4
Azure AI Infrastructure
Answrs VerdictSpecs are documented in detail, but the price is not on the pages we read.
Price: Not published on the pages we read; the Linux virtual machines pricing page we fetched lists no ND H100 v5 rateND H100 v5: Starts with a single VM with 8 NVIDIA H100 GPUs and can scale to thousands of GPUs with 3.2 Tbps of interconnect bandwidth per VMVM specs: The Standard_ND96isr_H100_v5 size has 96 vCPUs, 1,900 GiB of memory and 8 NVIDIA H100 GPUs with 80 GB eachReach: Azure says it has over 60 datacenter regions, more than any other cloud provider; this is Microsoft describing itself
Azure AI Infrastructure has no price on the pages we read. The ND H100 v5 series starts with a single VM with 8 NVIDIA H100 GPUs and scales to thousands of GPUs with 3.2 Tbps of interconnect bandwidth per VM. The Standard_ND96isr_H100_v5 size has 96 vCPUs and 1,900 GiB of memory, with 80 GB per H100. Azure says it has over 60 datacenter regions, more than any other cloud provider, which is Microsoft describing itself.
Go ifTeams already on Azure that want GPU virtual machines with InfiniBand networking
Skip ifYou need a price from the pages we read
Why #4 over #5: It documents VM specs in detail, while NVIDIA DGX Station lists no way to rent or price.
5
NVIDIA DGX Station
Answrs VerdictLarge GPU memory in a desk-side system, but no price is listed.
Price: Not listed on the page, which says to contact a partner to orderSuperchip: The NVIDIA GB300 Grace Blackwell Ultra Desktop Superchip, with one Blackwell Ultra GPU and one 72-core Grace CPUMemory: 252 GB of HBM3e GPU memory at 7.1 TB/s plus 496 GB of LPDDR5X, for 748 GB of coherent memoryPerformance: Up to 20 petaFLOPS of AI compute performance
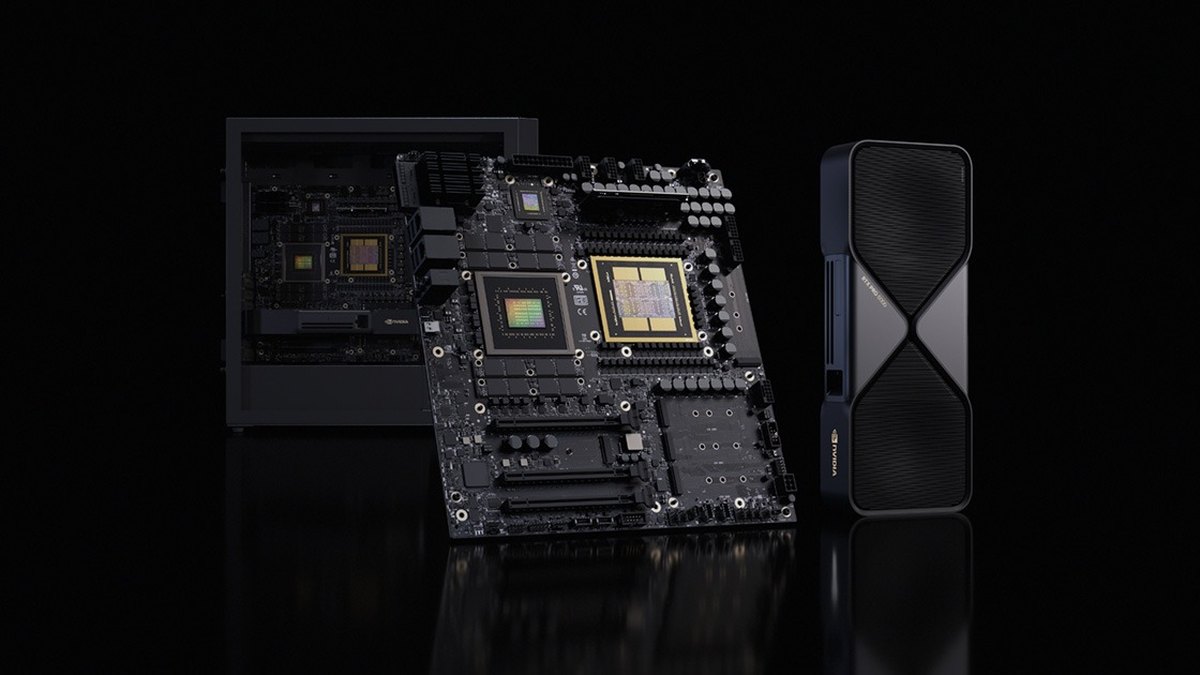
NVIDIA DGX Station is built on the GB300 Grace Blackwell Ultra Desktop Superchip, with one Blackwell Ultra GPU and one 72-core Grace CPU. It has 252 GB of HBM3e GPU memory at 7.1 TB/s plus 496 GB of LPDDR5X, for 748 GB of coherent memory, and up to 20 petaFLOPS of AI compute. No price is listed; the page says to contact a partner to order.
Go ifTeams that want a desk-side system with large GPU memory instead of renting
Skip ifYou need a published price or immediate availability
Why #5 over #6: It lists more memory and compute than DGX Spark, which has 128 GB and up to 1 PFLOP of FP4.
6
NVIDIA DGX Spark
Answrs VerdictA small local system with full specs, but no price on its page.
Price: Not listed on the page, which points buyers to the NVIDIA MarketplaceSuperchip: The NVIDIA GB10 Grace Blackwell Superchip with a 20-core Arm CPUMemory: 128 GB of LPDDR5X coherent unified memory at 273 GB/s; a 64 GB configuration is sold only through OEM partnersPerformance: Up to 1 PFLOP of FP4 tensor performance, which NVIDIA says is theoretical and assumes sparsityLinking: Two units connect with one QSFP cable for 256 GB of combined memory and models up to 400B parameters
NVIDIA DGX Spark uses the GB10 Grace Blackwell Superchip with a 20-core Arm CPU and 128 GB of LPDDR5X unified memory at 273 GB/s. It offers up to 1 PFLOP of FP4 tensor performance, which NVIDIA says is theoretical and assumes sparsity. Two units link with one QSFP cable for 256 GB of combined memory and models up to 400B parameters. No price is on the page, which points buyers to the NVIDIA Marketplace.
Go ifDevelopers who want a small local AI system they can link in pairs
Skip ifYou need a published price from the product page
Why #6 over #7: It documents memory and linking in full, while AMD Instinct MI400 lists no rental route.
7
AMD Instinct MI400 Series
Answrs VerdictRack-scale specs are documented, but there is no price or rental route on the page.
Price: Not published on the pageLineup: The Helios rackscale solution is powered by 72 AMD Instinct MI455X GPUs, and the MI430X GPU is for sovereign AI and HPCRack performance: Helios offers up to 2.9 exaFLOPS peak OCP MXFP4 and 1.4 exaFLOPS peak OCP MXFP8Memory: Helios has 31 TB of HBM4 memory and 1.67 PB/s of memory bandwidth
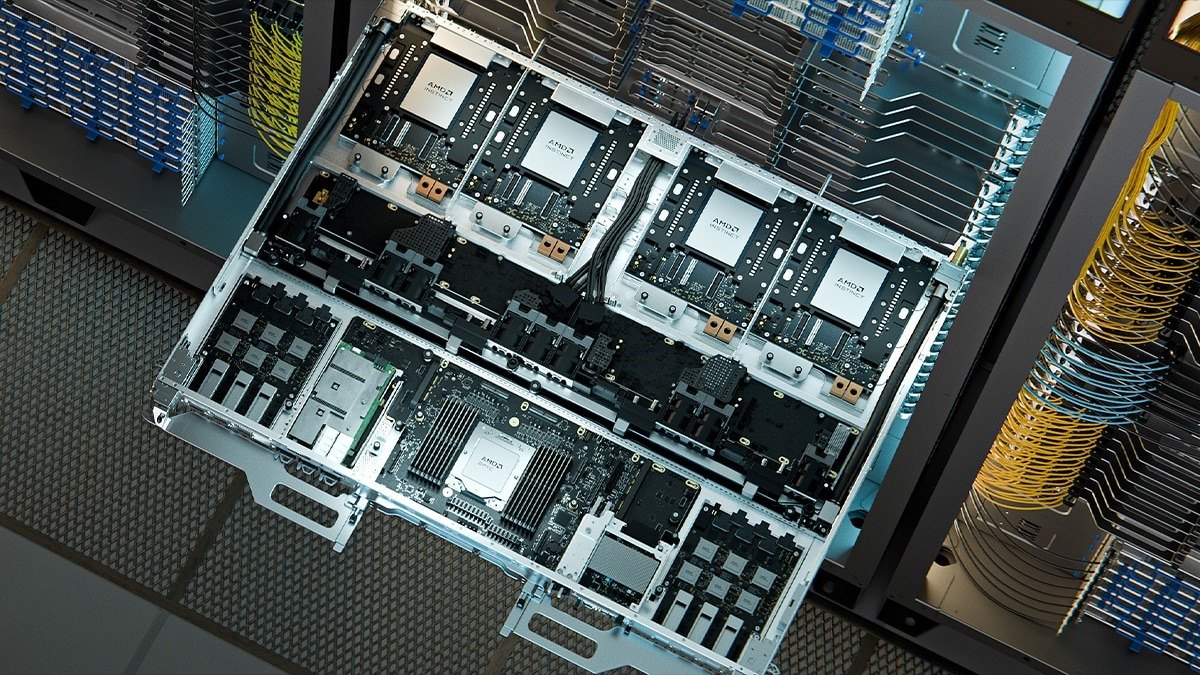
The AMD Instinct MI400 Series page describes the Helios rackscale solution with 72 AMD Instinct MI455X GPUs, and the MI430X GPU for sovereign AI and HPC. Helios offers up to 2.9 exaFLOPS peak OCP MXFP4, 1.4 exaFLOPS peak OCP MXFP8, 31 TB of HBM4 memory and 1.67 PB/s of memory bandwidth. No price is published.
Go ifBuyers planning rack-scale AI who want an AMD ROCm-based alternative
Skip ifYou want to rent by the hour or see a price
Why #7 over #8: It lists rack-level memory and speed, while Cerebras CS-3 gives only transistor and cluster figures.
8
Cerebras CS-3
Answrs VerdictWafer-scale specs from a 2024 post; the maker now promotes the CS-4.
Price: Not stated for the CS-3 system; the pricing page offers a Developer tier with a one-time $5 promotional credit that expires after 30 daysChip: Over 4 trillion transistors, which the March 12, 2024 launch post says is 57x more than the largest GPUScale: Up to 2048 CS-3 systems can be linked, for 256 exaflops of AI compute in a full clusterNewer system: Its system page now describes the CS-4, which it says has up to 10x more throughput per watt than the CS-3Access: Cerebras Inference is also available through AWS Marketplace, OpenRouter, Hugging Face and Vercel
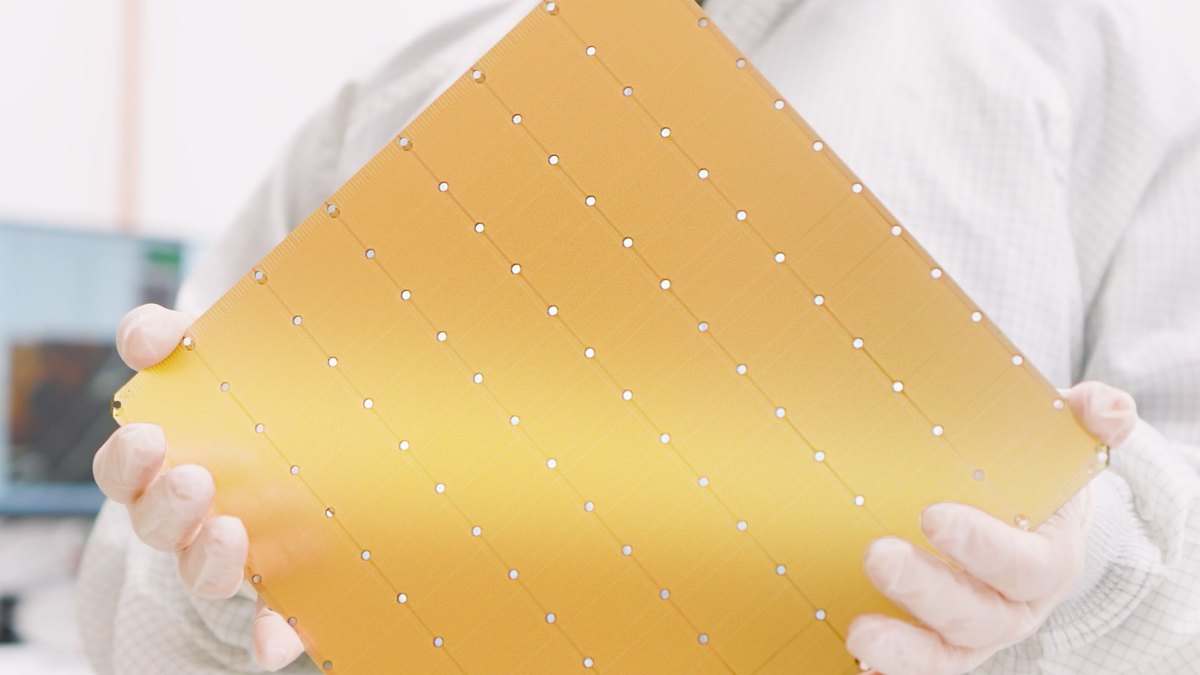
Cerebras CS-3 has over 4 trillion transistors, which its March 12, 2024 launch post says is 57x more than the largest GPU, and up to 2048 systems can be linked for 256 exaflops of AI compute. No CS-3 price is stated. Cerebras Inference is available through AWS Marketplace, OpenRouter, Hugging Face and Vercel, and its Developer tier gives a one-time $5 promotional credit that expires after 30 days. The system page now describes the CS-4, with up to 10x more throughput per watt than the CS-3.
Go ifTeams that want wafer-scale hardware or inference through a partner marketplace
Skip ifYou want a published system price
Why #8 over #9: It gives transistor and cluster figures, while Intel Gaudi 3 gives only relative performance.
9
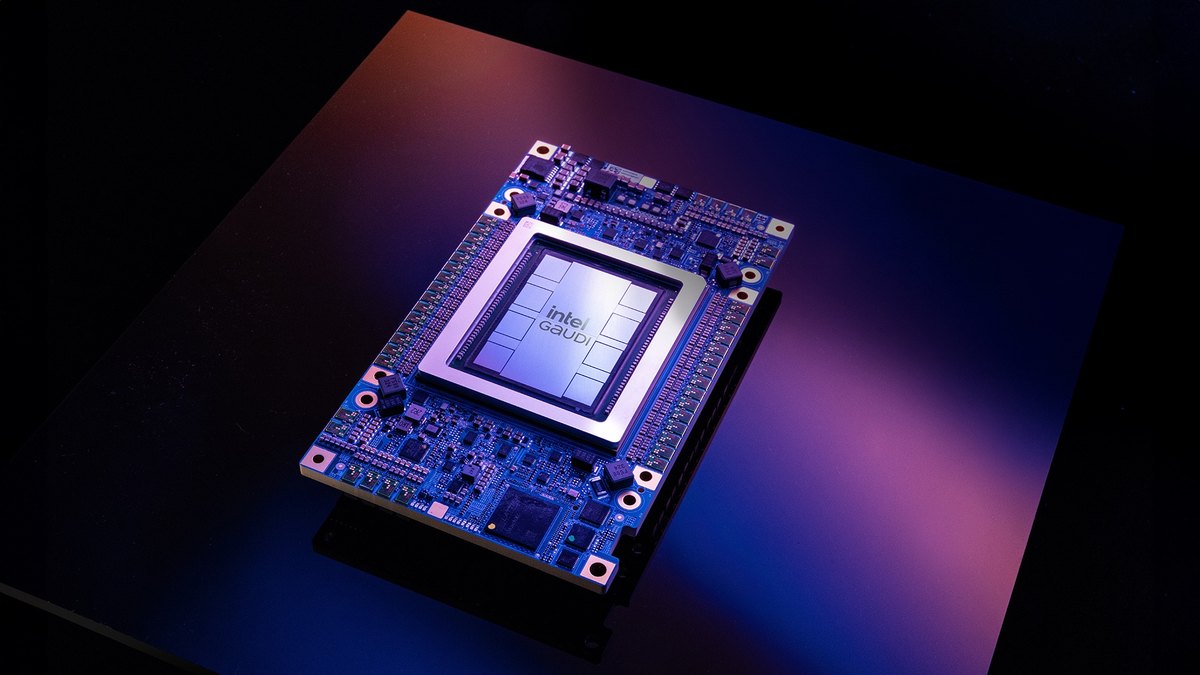
Intel Gaudi 3
Answrs VerdictOnly relative performance is on the page; no memory, absolute speed or price.
Price: Not listed on the pageCompute: Up to 2x AI compute (FP8) and up to 4x (BF16) versus Intel Gaudi 2, with no absolute figures on the pageNetworking: Up to 2x network bandwidth versus Gaudi 2; a footnote lists 1200 GB/s of open standard RoCE against 900 GB/s of NVLink on an NVIDIA H100Form factor: The HL-338 PCIe card uses a standard PCIe Gen5 form factor and standard Ethernet; OEM links go to Dell, HPE and Supermicro
Intel Gaudi 3 lists up to 2x AI compute (FP8) and up to 4x (BF16) versus Gaudi 2 and up to 2x network bandwidth, with no absolute figures. A footnote lists 1200 GB/s of open standard RoCE against 900 GB/s of NVLink on an NVIDIA H100. The HL-338 PCIe card uses a standard PCIe Gen5 form factor and standard Ethernet, with OEM links to Dell, HPE and Supermicro. No price is listed.
Go ifTeams that want standard Ethernet networking and OEM server options
Skip ifYou need memory capacity or absolute throughput from the product page
Why #9 over #10: It names OEM routes and a card form factor, while NVIDIA DGX SuperPOD gives no per-system specs.
10
NVIDIA DGX SuperPOD
Answrs VerdictA broad platform, but the page gives no price and no per-system specs.
Price: Not published; the page directs visitors to Get DGX and a Talk to Us formWhat it is: A full-stack data center platform combining computing, storage, networking, software and infrastructure managementSystems: Options listed include DGX H200, B200, B300, GB200 and GB300 systems, plus newer Rubin-based DGX Vera Rubin NVL72 and DGX Rubin NVL8Scale: The only scale claim is scaling to tens of thousands of NVIDIA GPUs; the page gives no per-system memory or FLOPS
NVIDIA DGX SuperPOD is a full-stack data center platform combining computing, storage, networking, software and infrastructure management. Listed systems include DGX H200, B200, B300, GB200 and GB300, plus the newer DGX Vera Rubin NVL72 and DGX Rubin NVL8. The only scale claim is scaling to tens of thousands of NVIDIA GPUs, and the page gives no price or per-system memory or FLOPS; visitors are directed to Get DGX and a Talk to Us form.
Go ifEnterprises building their own AI data center with NVIDIA support and certified storage partners
Skip ifYou need specs or a price before talking to sales
How we ranked these
We ranked AI infra options by how much of what a buyer needs each vendor's own pages publish: a price, hardware specs such as memory, and how far the price list reaches. Options with a fuller price list rank higher, and ties go to the one with more published specs. Rented GPU clouds and bought systems are not priced alike, so prices are quoted exactly as each page states them and are not compared across units. Where a price is not published we say so. Facts are taken from each maker's own published information; check the official site before you buy.
Questions people ask
What does "AI infra options" mean on this page?
It means ways to get compute for AI work: GPU clouds you rent by the hour (Lambda, CoreWeave, Oracle, Azure), and systems you buy or order for your own site (NVIDIA DGX Station, DGX Spark and DGX SuperPOD, AMD Instinct MI400, Cerebras CS-3 and Intel Gaudi 3). It does not cover software tools.
Which AI infra option publishes the most pricing?
Lambda Cloud: its page lists per-GPU-hour prices from $0.69 to $7.99 for instances, plus 1-Click Cluster prices for HGX B200 and H100 at 16, 64 and 256 GPUs. CoreWeave also lists on-demand and spot prices.
How much does an NVIDIA H100 cost per hour on a GPU cloud?
Lambda lists an HGX H100 instance at $4.59 per GPU-hour, and CoreWeave lists an 8-GPU HGX H100 instance at $49.24 per hour; the units differ, so compare the per-GPU figure with care.
Can you buy a small AI system instead of renting?
NVIDIA DGX Spark has 128 GB of unified memory and up to 1 PFLOP of FP4 performance, and DGX Station has 252 GB of HBM3e GPU memory. Neither product page lists a price.
GPU memory per accelerator stated on each vendor page (GB; the DGX Station figure is HBM3e GPU memory, the others are per-GPU memory in the listed configuration) at a glance
GPU memory per accelerator stated on each vendor page (GB; the DGX Station figure is HBM3e GPU memory, the others are per-GPU memory in the listed configuration), as published by each maker. Picks without a published figure are left off.