The 10 Best AI Tools for End-to-End Testing in 2027
By Kory White · Updated Oct 2026 · 5 min read
Direct answer
mabl is the best AI tool for end-to-end testing: its agents create, run, analyze and maintain tests across web, mobile and APIs, with auto-healing, though it does not publish a price. testRigor is #2 for plain-English tests, and Functionize is #3 with a free plan and paid plans from $20 a month.
Starter free; Team $67 a month billed annually at $799; Business $267 a month billed annually at $3,199
Developers already on Cypress who want AI prompts and Cloud analytics added
Pick by what you want
Best overall
mabl
Best plain-English tests
testRigor
Best free start
Functionize
Best cheapest paid agent
KaneAI
Best visual AI
Applitools
The ranking
1
mabl
Answrs VerdictThe most complete agentic end-to-end platform.
Price: Not published; the pricing page is a request-a-quote formAgentic testing: Specialized agents work together to create, run, analyze and maintain tests across web, mobile and APIsAuto-healing: Advanced auto-healing and agentic test runtime recoveryScope: Unlimited apps, environments and workspaces, with unlimited test run concurrency
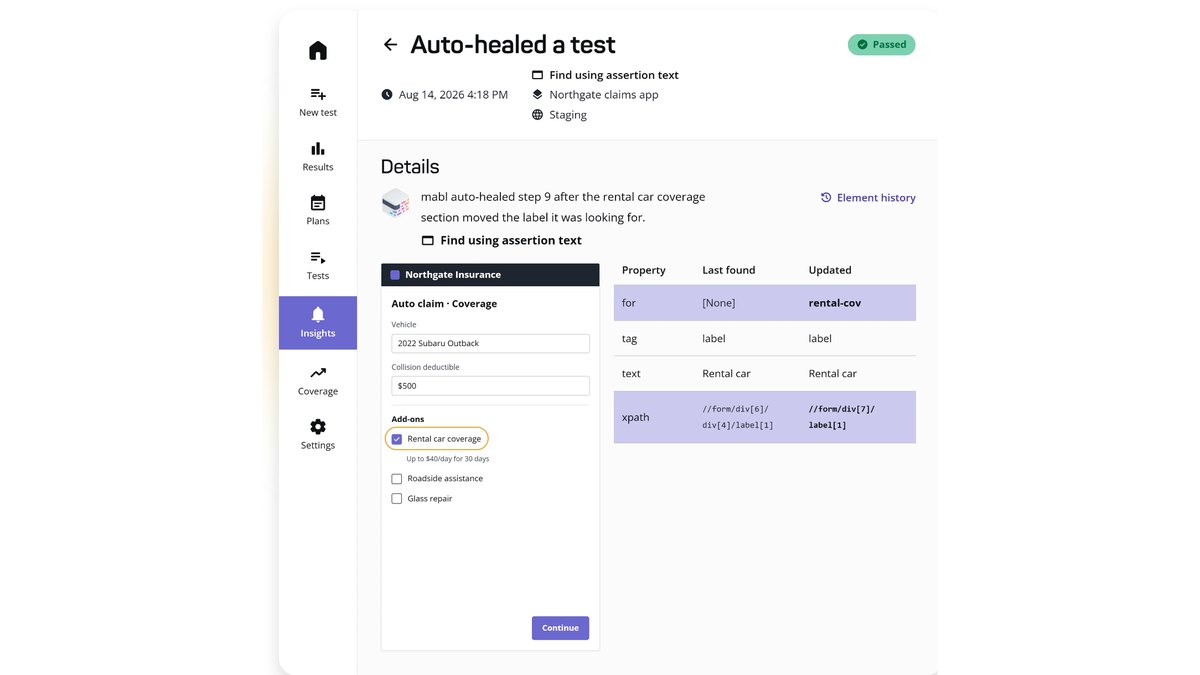
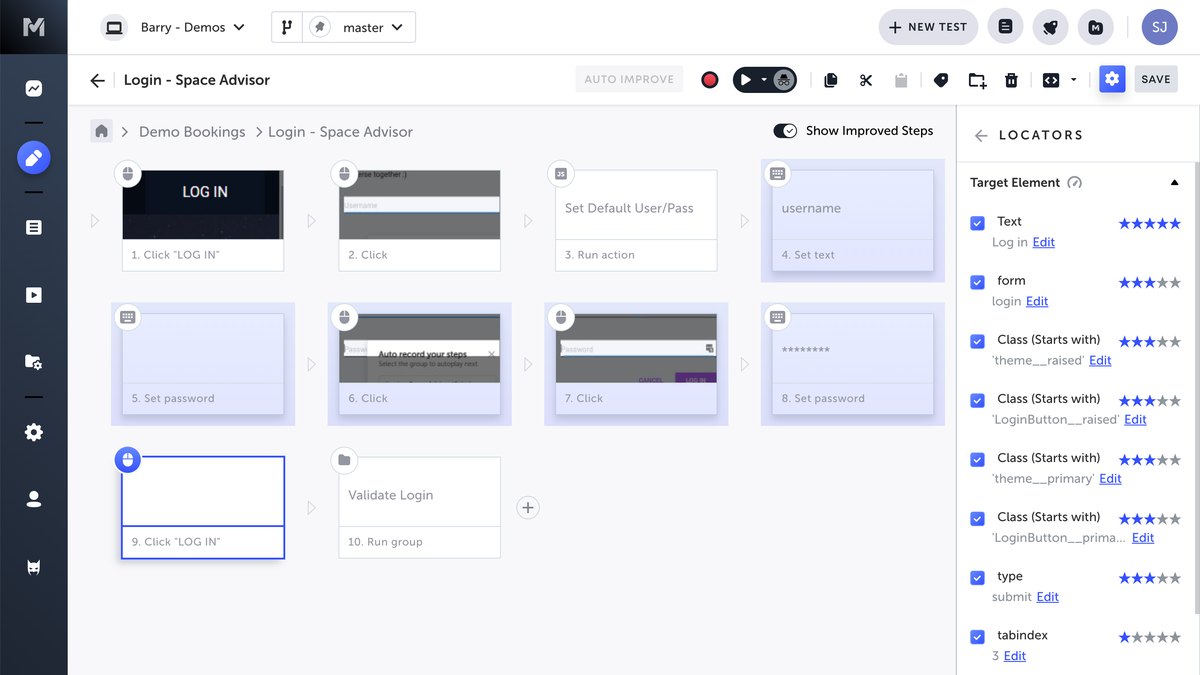
mabl describes its platform as specialized agents that work together to create, run, analyze and maintain tests across web, mobile and APIs. Its pricing page lists advanced auto-healing, agentic test runtime recovery and automatic failure summaries, with unlimited apps, environments and test run concurrency. Pricing is a request-a-quote form, so no figure is published.
Go ifTeams that want one agentic platform for web, mobile and API tests with auto-healing
Skip ifYou need a published price you can budget from
Why #1 over #2: It covers web, mobile and API in one platform, while Tricentis Testim centers on locators.
2
testRigor
Answrs VerdictThe best plain-English test writer.
Price: Not published; the vendor says it charges only for the servers that run tests in parallelPlain-English tests: Write tests in free-flowing plain English; testRigor translates an instruction like purchase a Kindle into specific stepsGenerative AI: Markets itself as generative AI-based test automation, with AI agents and AI-based self-healingControl: You can correct and expand the generated steps
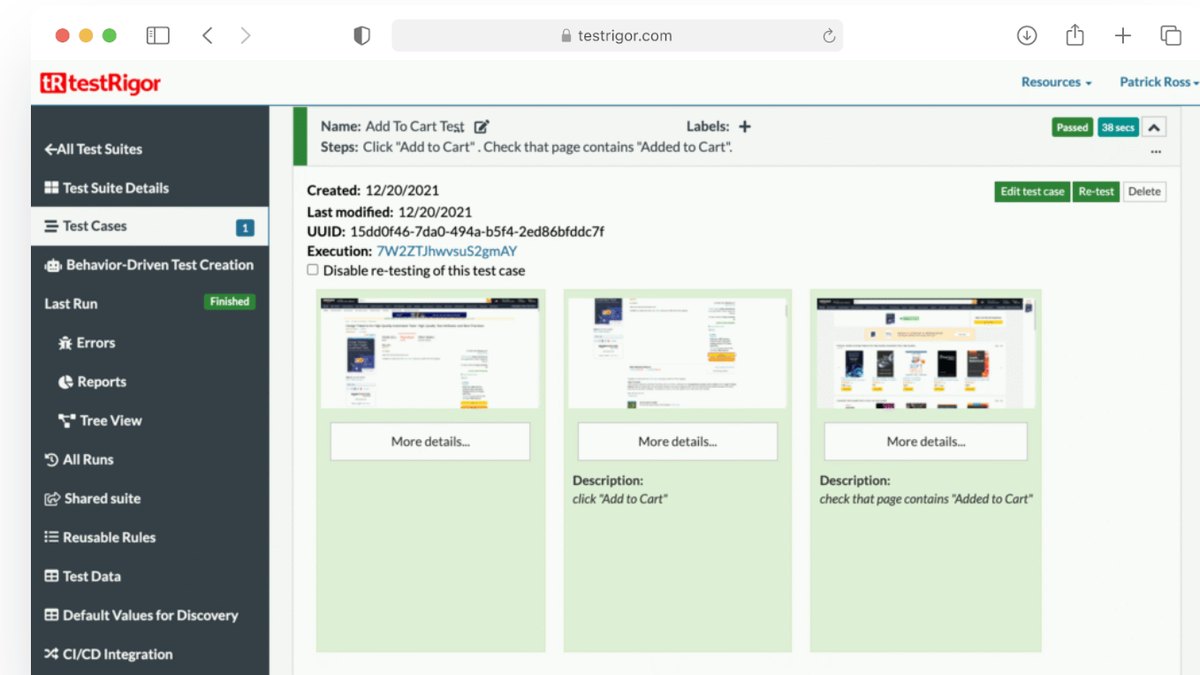
testRigor lets you write tests in free-flowing plain English and translates an instruction like purchase a Kindle into specific steps, which you can correct and expand. It markets generative AI, AI agents and AI-based self-healing. The vendor says it charges only for the servers that run tests in parallel, and publishes no price list.
Go ifManual testers and analysts who want to write end-to-end tests without code
Skip ifYou need a published price list
Why #2 over #3: Its plain-English authoring needs no code, while Cypress is aimed at developers.
3
Functionize
Answrs VerdictThe best low-cost agentic web testing start.
Price: Free $0; Growth $20 a month; Scale $100 a month; Enterprise customStudio: Functionize Studio is an independent testing agent for your full web UI workflow: describe what to test and it builds, runs and keeps tests greenFree plan: 800,000 credits a month, all agent capabilities and 5 parallel runsPaid credits: Growth 3,200,000 credits a month; Scale 20,000,000 credits and 10 parallel runs
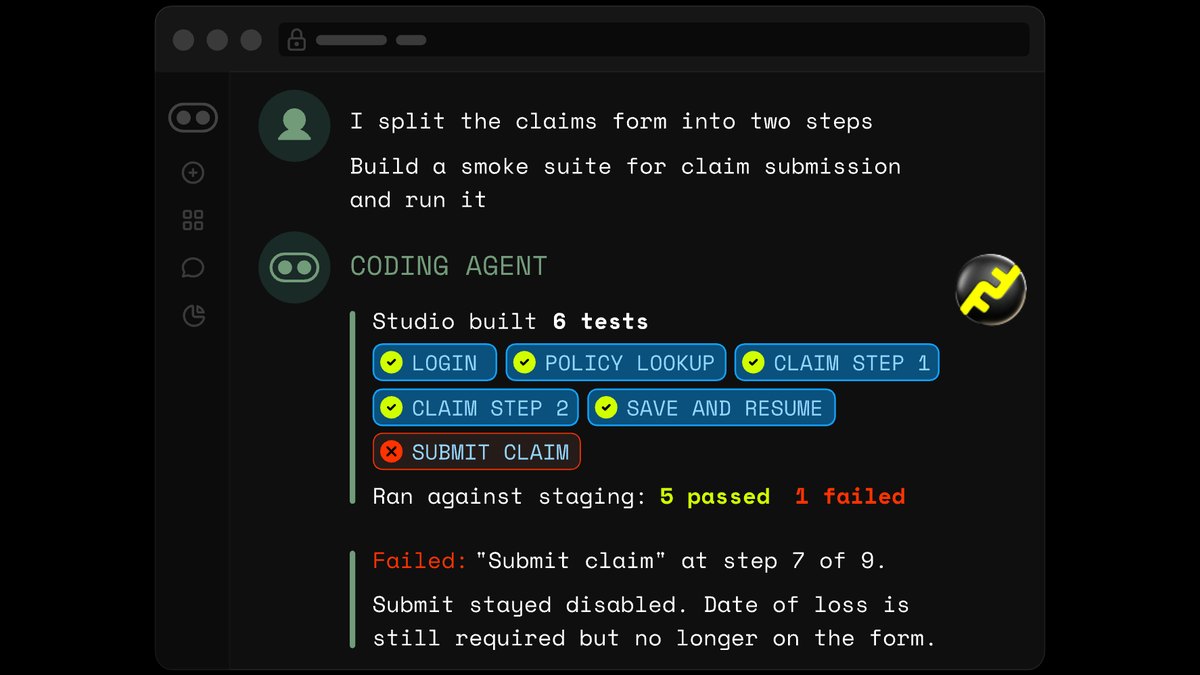
Functionize Studio is an independent testing agent for your full web UI workflow: you describe what to test and it builds, runs and keeps tests green. The Free plan gives 800,000 credits a month, all agent capabilities and 5 parallel runs. Growth is $20 a month, Scale is $100 a month with 10 parallel runs, and Enterprise is custom.
Go ifTeams that want an AI agent to build and run web UI tests, starting on a free plan
Skip ifYou need mobile app testing
Why #3 over #4: It starts free and paid plans start at $20 a month, while Applitools Starter is $667 a month.
4
QA Wolf
Answrs VerdictThe best pay-per-run end-to-end service.
Price: $1 per web test run; $2 per mobile or desktop runBilling: Pay per run with unlimited AI included and no AI credit or token billsAI repair: If a test fails three attempts, an AI agent investigates and either repairs it or files a bug reportRetries: Each run is attempted up to 3 times for free to catch flakes
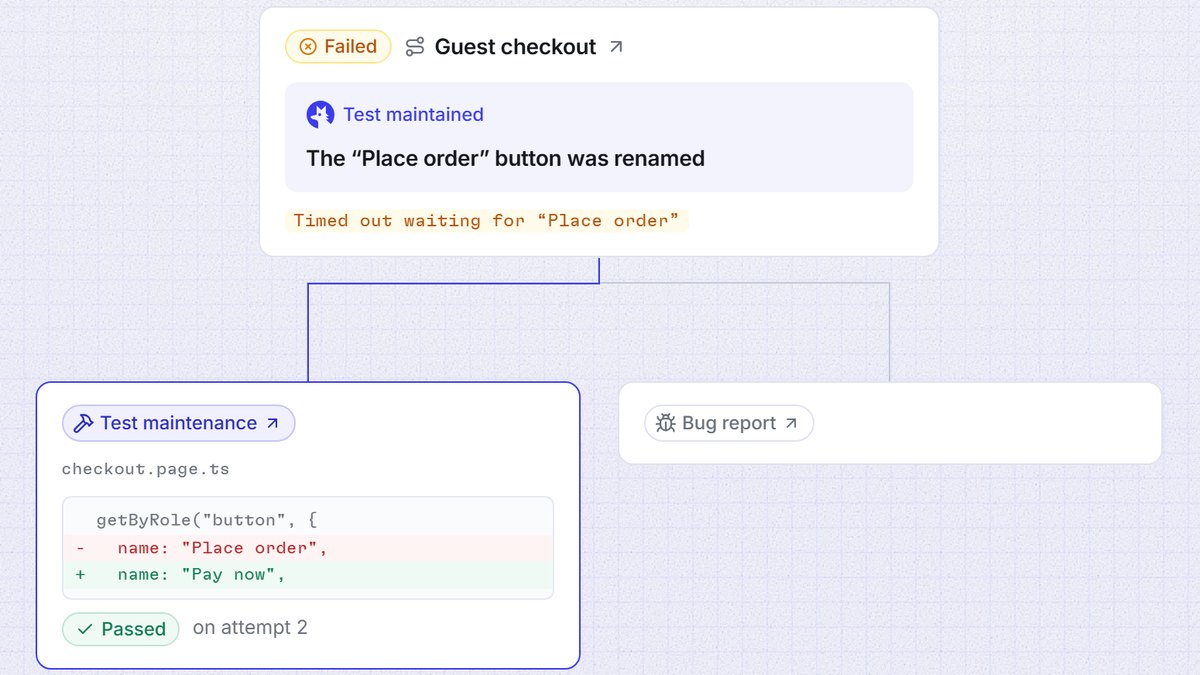
QA Wolf charges per test run: $1 on web and $2 on mobile or desktop, with unlimited AI included and no AI credit bills. Each run is attempted up to 3 times for free to catch flakes, and if a test still fails an AI agent investigates and either repairs it or files a bug report.
Go ifTeams that want end-to-end runs billed per run with AI maintenance included
Skip ifYou want a flat monthly subscription
Why #4 over #5: Its per-run billing includes AI maintenance, while Momentic meters AI steps in credits.
5
Momentic
Answrs VerdictThe best usage-priced AI QA engineer.
Price: Free $0 with 2,000 credits a month; Pay-as-you-go $125 a month plus usage; Enterprise customAI QA engineer: Mo is an AI QA engineer that tests your app end to end and verifies critical flows from a promptAI step cost: A normal test step costs 1 credit; a step generated by an AI action or failure recovery costs 2 creditsMobile: Pay-as-you-go includes 5 Android emulators and 5 iOS simulators
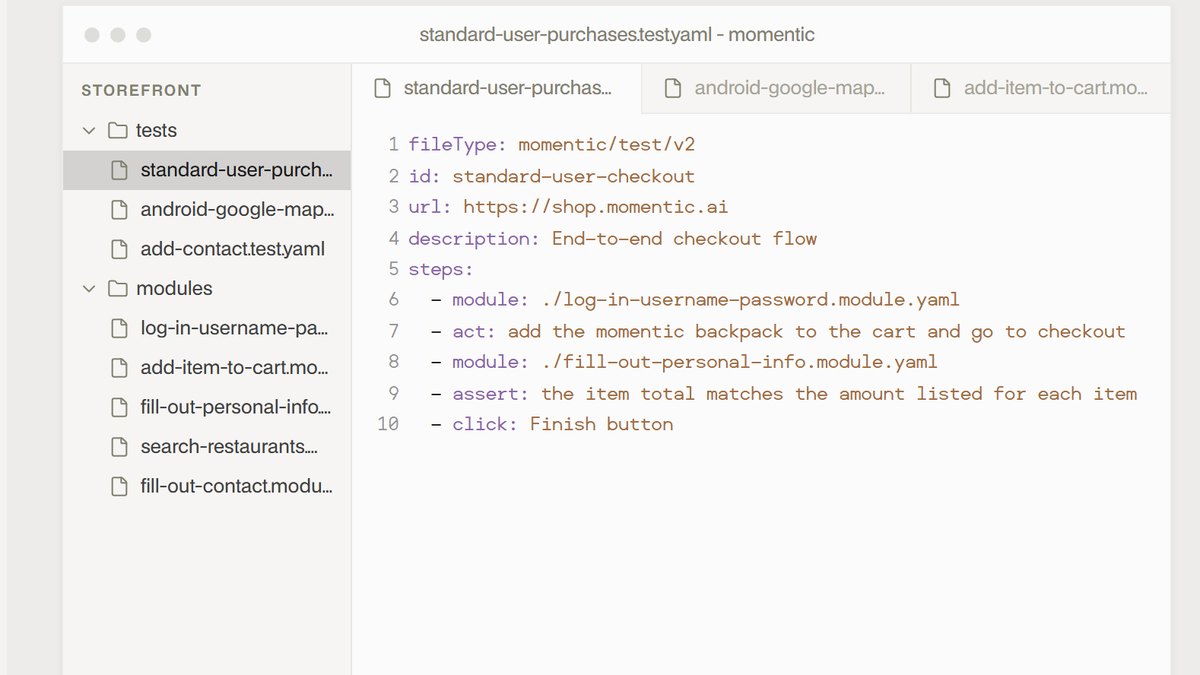
Momentic’s Mo is an AI QA engineer that tests your app end to end and verifies critical flows from a prompt. A normal step costs 1 credit and a step generated by an AI action or failure recovery costs 2. Free is $0 with 2,000 credits a month; Pay-as-you-go is $125 a month plus usage and includes 5 Android emulators and 5 iOS simulators.
Go ifDeveloper-led teams that want AI-driven web and mobile tests kept in code
Skip ifYou want fixed pricing with no usage metering
Why #5 over #6: It includes mobile emulators and simulators in the plan, while Functionize focuses on web UI.
6
KaneAI
Answrs VerdictThe cheapest paid AI end-to-end agent.
Price: Starter $17 per agent per month billed annually; Pro $89; Max $179; Enterprise customNatural language: Describe a test in plain English and KaneAI plans, authors, runs and evolves it across web and mobile appsStarter credits: Starter includes 2,000 credits and local authoring through Kane CLIHigher tiers: Pro adds 12,000 credits and cloud web authoring; Max adds 25,000 credits and cloud web plus mobile authoring
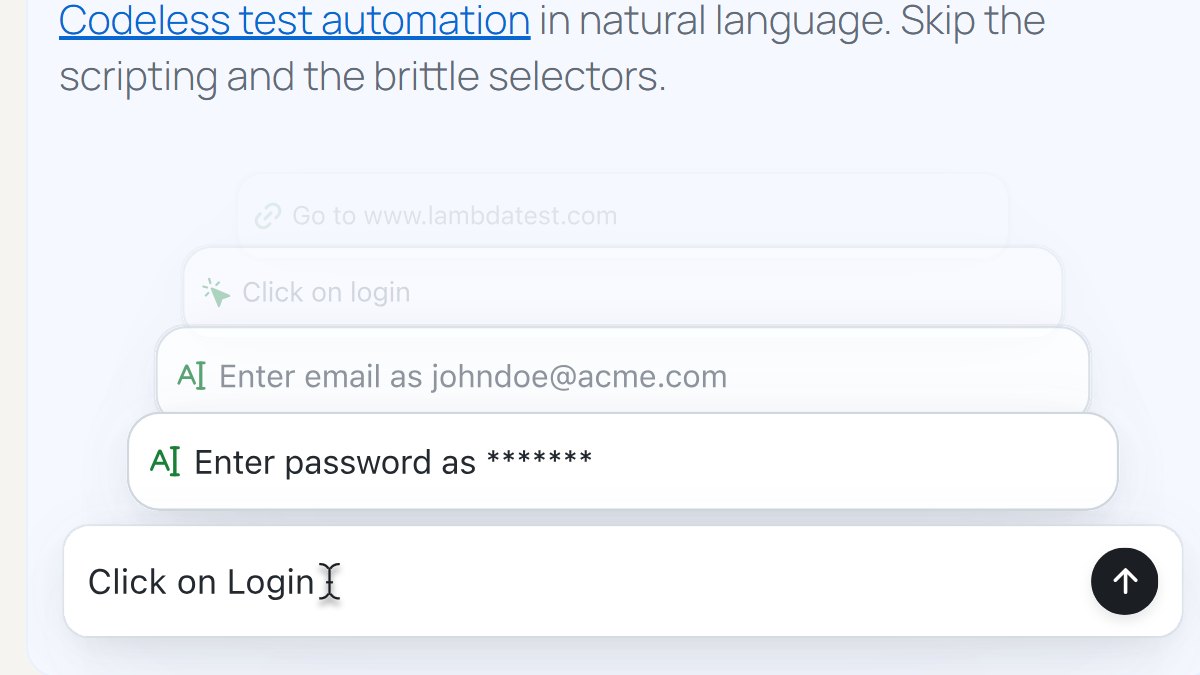
KaneAI, from TestMu AI (formerly LambdaTest), lets you describe a test in plain English and plans, authors, runs and evolves it across web and mobile apps. Starter is $17 per agent per month billed annually with 2,000 credits and local authoring through Kane CLI; Pro is $89 with 12,000 credits and Max is $179 with 25,000 credits.
Go ifTeams that want a cheap per-agent entry to natural-language end-to-end testing
Skip ifYou need monthly billing, since the listed prices are billed annually
Why #6 over #7: Its $17 Starter plan is far cheaper than Applitools Starter at $667 a month.
7
Applitools
Answrs VerdictThe best visual layer for end-to-end tests.
Price: Starter $667 a month, paid annually; Professional and Enterprise by quoteVisual AI: Starter includes visual validation with Visual AI and a Visual AI MCP serverStarter limits: Unlimited users and 100,000 component checkpoints or 1,000 page checkpointsProfessional: Adds AI-driven functional testing and NLP-based test authoring
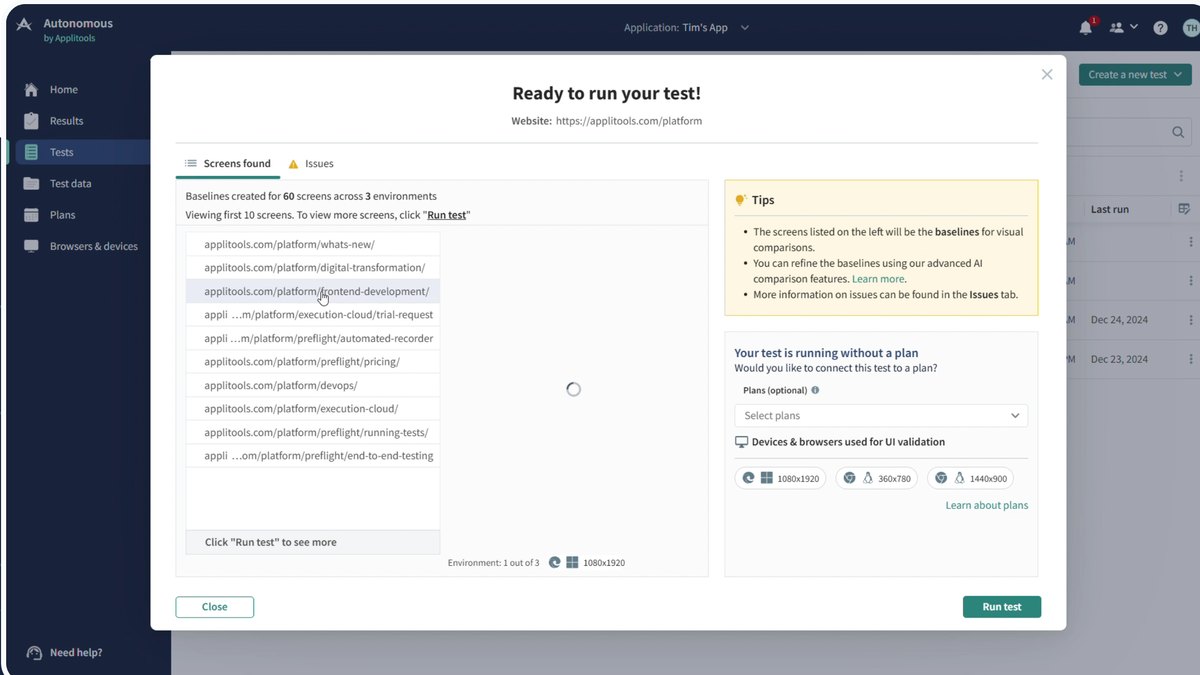
Applitools is built around Visual AI. Starter is $667 a month, paid annually, with unlimited users, 100,000 component checkpoints or 1,000 page checkpoints, and a Visual AI MCP server. Professional adds AI-driven functional testing and NLP-based test authoring and is priced by quote.
Go ifTeams that need AI to catch visual regressions across browsers and devices
Skip ifYou want a low entry price
Why #7 over #8: It is the one tool here built on visual validation, while Tricentis Testim relies on locators.
8
Tricentis Testim
Answrs VerdictThe most established self-healing locators.
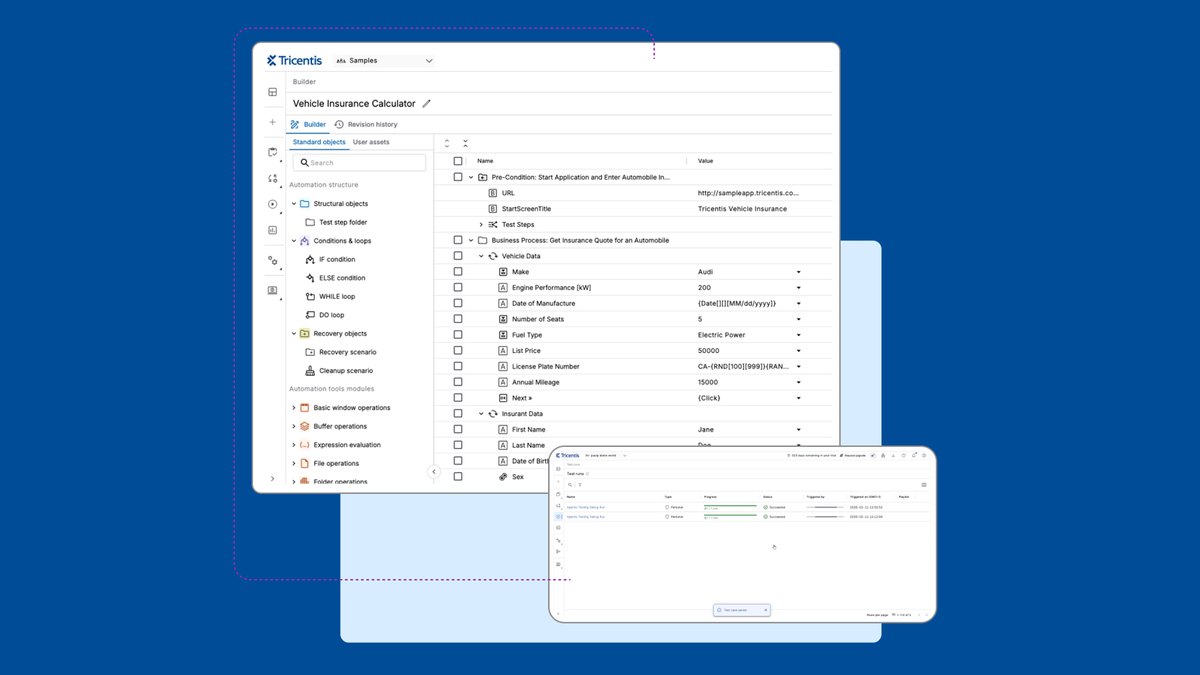
Price: Not published in the sources reviewedAI locators: Uses AI-powered locators to reduce test failures and maintenanceWhen the UI changes: Testim recalculates the locator with AI, scores other matches against a confidence threshold and picks the best matchVision Locate: A custom-trained AI vision model analyzes a screenshot as a fallback when a mobile test fails
Tricentis Testim uses AI-powered locators to reduce test failures and maintenance. When an app changes it recalculates the locator with AI, scores other matches against a confidence threshold and picks the best one. On mobile, a custom-trained AI vision model analyzes a screenshot as a fallback. No price was found in the sources reviewed.
Go ifTeams whose web and mobile UI changes often and breaks scripted tests
Skip ifYou need a published price
Why #8 over #9: Its documented self-healing locators go deeper than Cypress’s prompt feature.
9
Tricentis Tosca
Answrs VerdictThe best end-to-end AI for enterprise stacks.
Price: Not published on the product pageAgentic Test Automation: AI agents generate complete end-to-end tests from plain-language descriptions and merge them with your existing Tosca assetsCoverage: 200+ technologies, including SAP, Oracle, Salesforce and webModel-based: A model-based approach separates the test model from the application so updates reach many test cases at once
Tricentis Tosca’s Agentic Test Automation has AI agents generate complete end-to-end tests from plain-language descriptions and merge them with your existing Tosca assets. It covers 200+ technologies including SAP, Oracle and Salesforce, and its model-based approach lets updates reach many test cases at once. No price is published on the product page.
Go ifEnterprises testing SAP, Oracle and Salesforce flows alongside web apps
Skip ifYou only test one modern web app
Why #9 over #10: It covers SAP, Oracle and Salesforce, which Cypress does not list.
10
Cypress
Answrs VerdictThe AI add-on for the open-source runner.
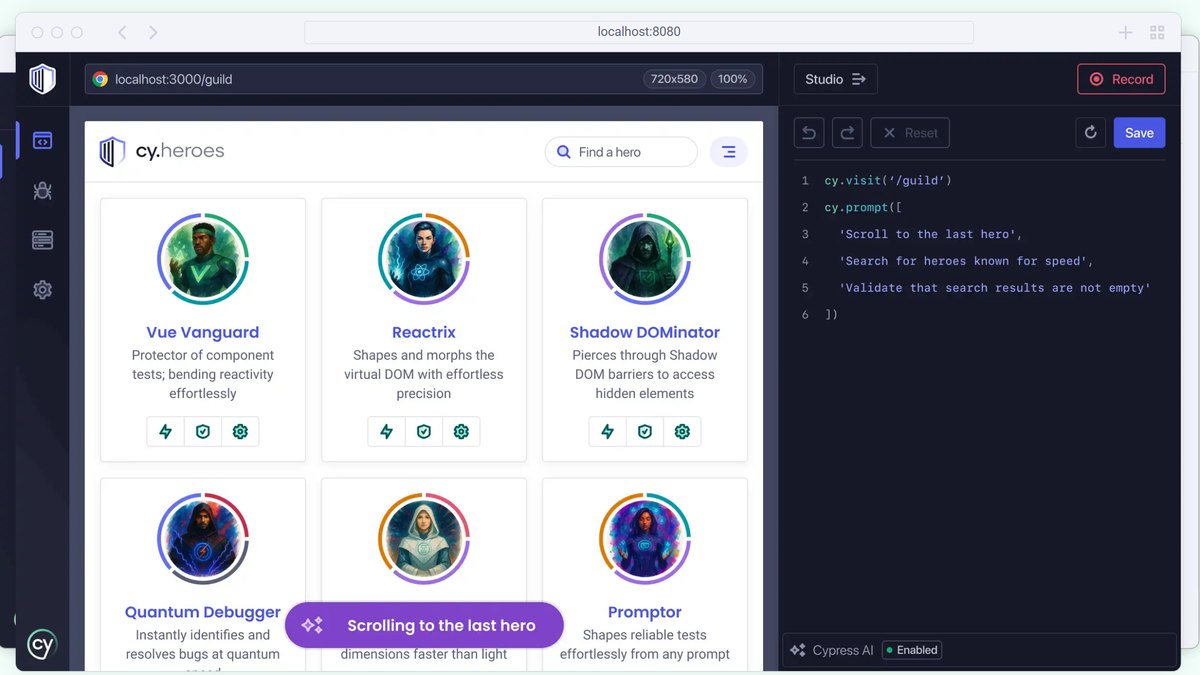
Price: Starter free; Team $67 a month billed annually at $799; Business $267 a month billed annually at $3,199Natural-language tests: Create self-healing tests with natural language prompts in the Cypress App and save the AI-generated test code at any timeStarter limits: 500 test results and 100 prompt executions a monthTeam limits: 120k test results and 9k prompt executions a year
Cypress adds AI to its open-source runner: in the Cypress App you can create self-healing tests with natural language prompts and save the AI-generated code. Starter is free with 500 test results and 100 prompt executions a month; Team is $67 a month billed annually at $799 and Business is $267 a month billed annually at $3,199.
Go ifDevelopers already on Cypress who want AI prompts and Cloud analytics added
Skip ifYou want a no-code tool for non-developers
How we ranked these
We ranked tools that use AI directly to create, run or maintain full-flow UI, browser and mobile tests, using each vendor’s own site. This page covers end-to-end testing, not API testing. Prices are the vendor’s published figures; tools with no published price say so and stay out of the chart. The chart uses one basis only: entry paid plans in USD per month billed annually. Vendor claims are not independently tested. Facts are taken from each maker's own published information; check the official site before you buy.
Questions people ask
What is the best AI tool for end-to-end testing?
mabl: its agents create, run, analyze and maintain tests across web, mobile and APIs, with auto-healing and runtime recovery. It does not publish a price.
Which AI end-to-end tool has a free plan?
Functionize has a Free plan with 800,000 credits a month and 5 parallel runs, Momentic has a Free plan with 2,000 credits, and Cypress Starter is free.
Can I write end-to-end tests in plain English?
Yes. testRigor and KaneAI both take plain-English instructions, and Tricentis Tosca generates tests from plain-language descriptions.
What is the cheapest paid AI testing agent?
KaneAI Starter at $17 per agent per month billed annually, then Cypress Team at $67 a month billed annually.
Entry paid plan, per month, billed annually (vendor pricing pages) at a glance
KaneAI Starter17 USD per month
Cypress Team67 USD per month
KaneAI Pro89 USD per month
Cypress Business267 USD per month
Applitools Starter667 USD per month
Entry paid plan, per month, billed annually (vendor pricing pages), as published by each maker. Picks without a published figure are left off.