The 10 Best Distributed Training Frameworks in 2027
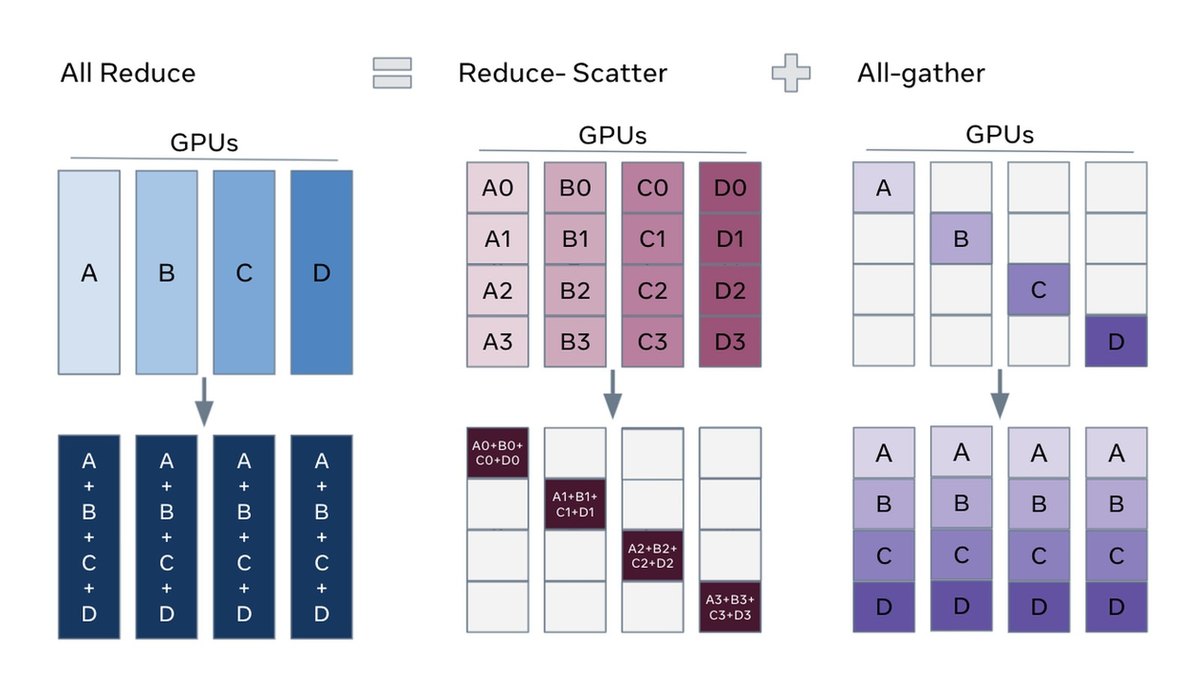
PyTorch FSDP is the best distributed training framework: it shards parameters, gradients and optimizer states across GPUs and is built into PyTorch. DeepSpeed is #2 and Megatron-LM is #3. The ranking is based on what each does for multi-GPU training, then on how recently each project shipped a release.
At a glance
| # | Pick | Price | Best for |
|---|---|---|---|
| 1 | PyTorch FSDP | Free; part of the open-source PyTorch repository on GitHub | Teams that want sharded training built into PyTorch itself |
| 2 | DeepSpeed | Free; Apache-2.0 license | Training very large models with ZeRO memory savings |
| 3 | Megatron-LM | Free; open-source code on GitHub | NVIDIA GPU teams building custom transformer training at scale |
| 4 | Hugging Face Accelerate | Free; Apache-2.0 license | Moving an existing PyTorch loop to many GPUs with minimal edits |
| 5 | Ray Train | Free; Apache-2.0 license | Running other frameworks’ training jobs on a cluster you manage with Ray |
| 6 | PyTorch Lightning | Free; Apache-2.0 license | Researchers who want less boilerplate and a switchable strategy |
| 7 | NVIDIA NeMo Automodel | Free; Apache-2.0 license | Fine-tuning Hugging Face models with PyTorch-native parallelism on NVIDIA GPUs |
| 8 | Colossal-AI | Free; Apache-2.0 license | Experimenting with many parallelism strategies in one library |
| 9 | MosaicML Composer | Free; Apache-2.0 license | FSDP training with elastic sharded checkpoints and streaming data |
| 10 | Horovod | Free; Apache-2.0 license | Maintaining an existing Horovod job that already works |
Pick by what you want
The ranking
PyTorch FSDP
PyTorch FSDP shards model parameters, gradients and optimizer states across GPUs, so models that cannot fit on one GPU can be trained. The current version, FSDP2, is built on DTensor, and the PyTorch tutorial says FSDP1 is deprecated. It is free and part of the open-source PyTorch repository; the latest release is v2.14.1, published Sep 30, 2026.
DeepSpeed
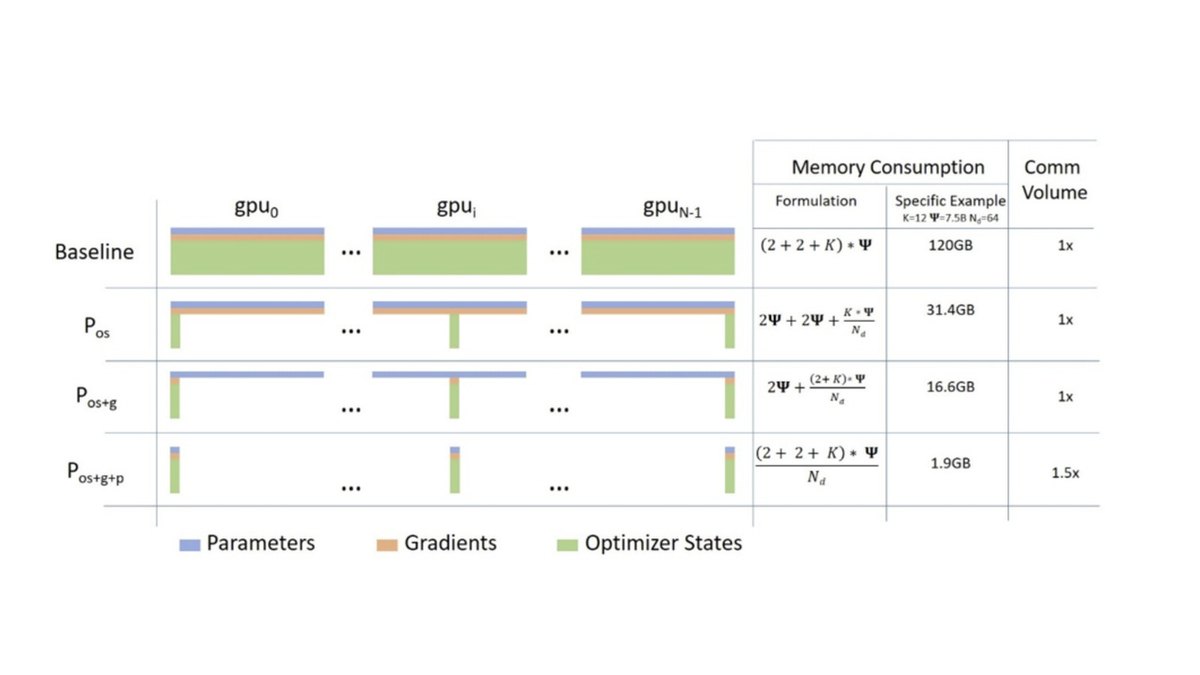
DeepSpeed is free under the Apache-2.0 license. Its README says it enabled language models such as MT-530B and BLOOM. The project has 43,245 GitHub stars as of Oct 20, 2026, and its latest release is v0.19.7, published Sep 16, 2026.
Megatron-LM
Megatron-LM, from NVIDIA, includes Megatron Core, a composable library with TP, PP, DP, EP and CP parallelism strategies and FP16, BF16, FP8 and FP4 mixed precision. The code is free on GitHub; the latest release is core_v0.19.2, published Sep 18, 2026.
Hugging Face Accelerate
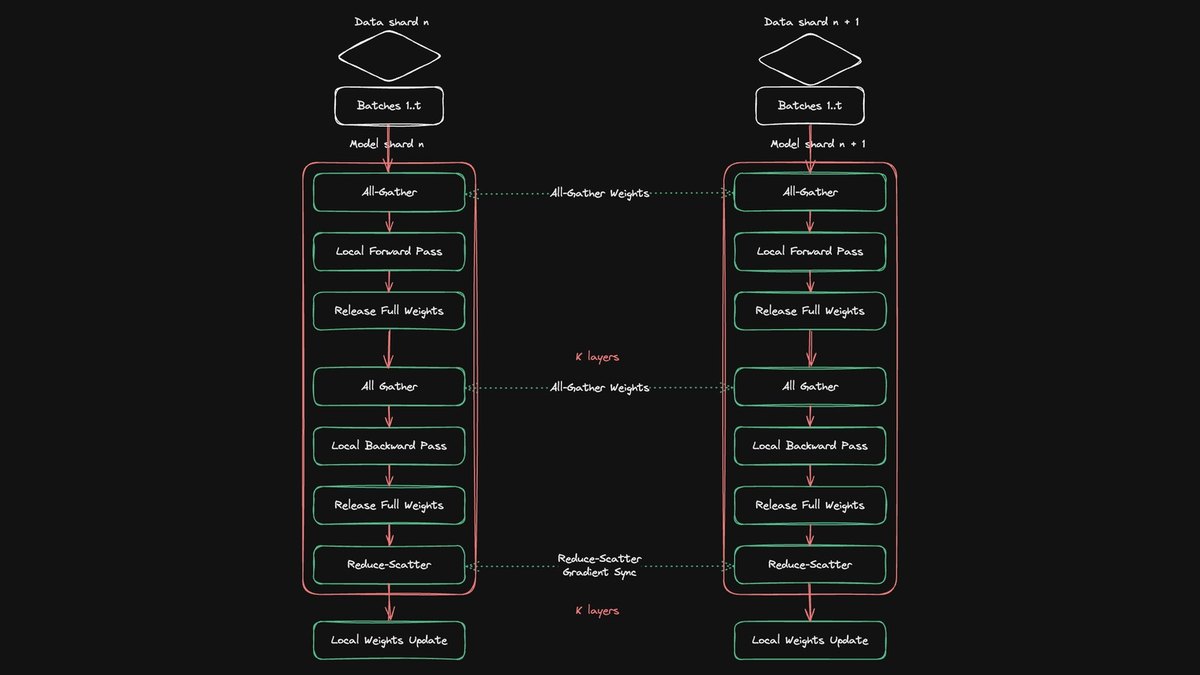
Hugging Face Accelerate says adding 5 lines to a standard PyTorch training script runs it on single or distributed setups, with easy-to-configure FSDP and DeepSpeed support. It is free under Apache-2.0; the latest release is v1.15.0, published Sep 9, 2026.
Ray Train
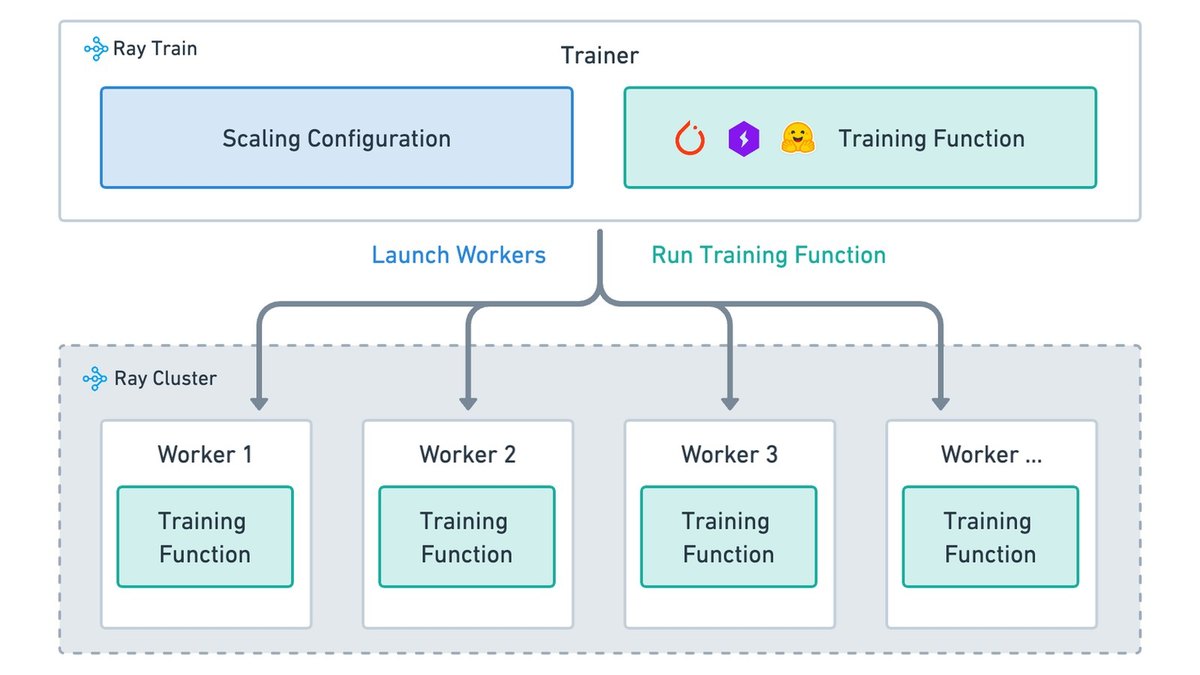
Ray Train scales training code from a single machine to a cluster of machines in the cloud. It supports PyTorch, TensorFlow, PyTorch Lightning, Keras, Hugging Face Transformers, Horovod, Hugging Face Accelerate, XGBoost, DeepSpeed and LightGBM. It is free under Apache-2.0; Ray 2.59.0 was published Oct 2, 2026.
PyTorch Lightning
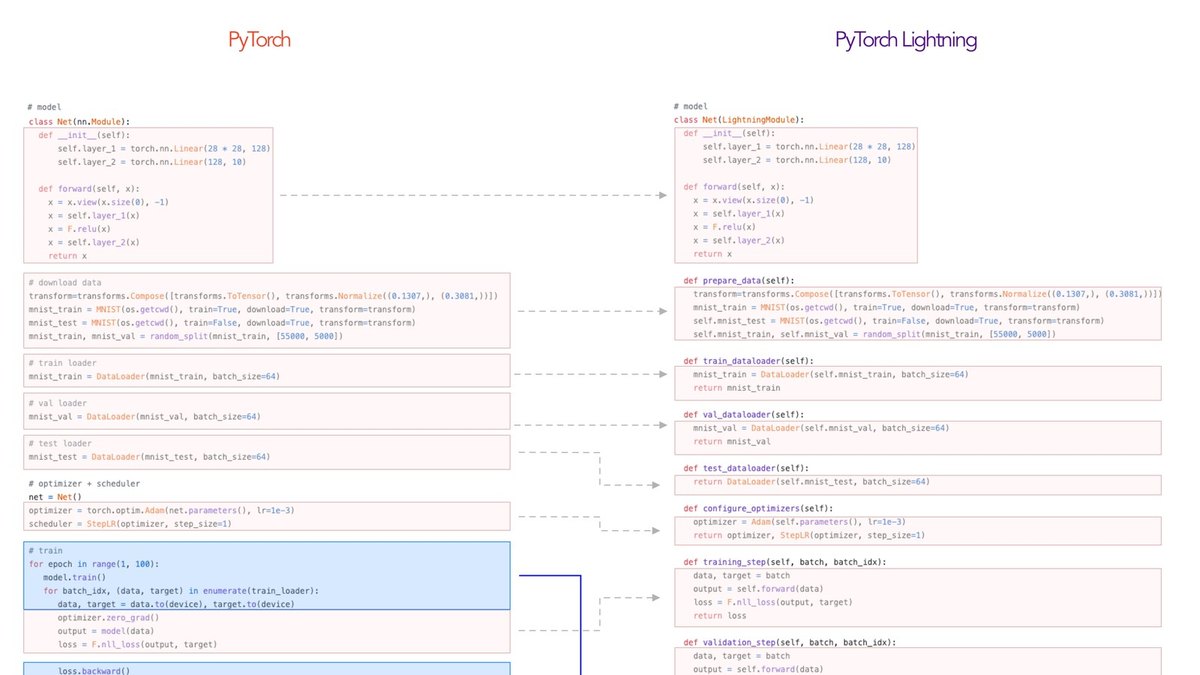
PyTorch Lightning says it can pretrain and finetune AI models on 1 or 10,000+ GPUs with zero code changes. Lightning Fabric lets you pick ddp, fsdp or deepspeed strategies. It is free under Apache-2.0 and has 31,418 GitHub stars as of Oct 20, 2026.
NVIDIA NeMo Automodel
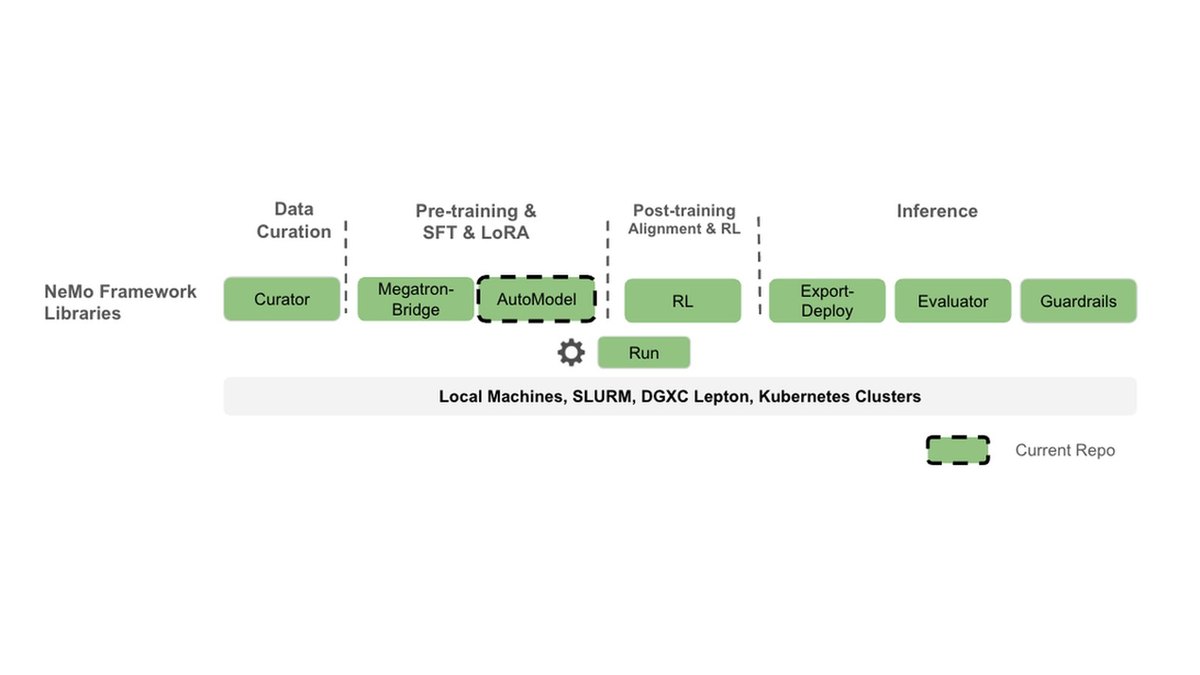
NVIDIA NeMo Automodel is a PyTorch distributed-native training library for LLMs and VLMs with out-of-the-box Hugging Face support. Its news items cite FSDP2, expert, pipeline and context parallelism. The older NeMo repository says it has pivoted to audio, speech and multimodal LLMs, so Automodel is the NeMo project to pick here. It is free under Apache-2.0.
Colossal-AI
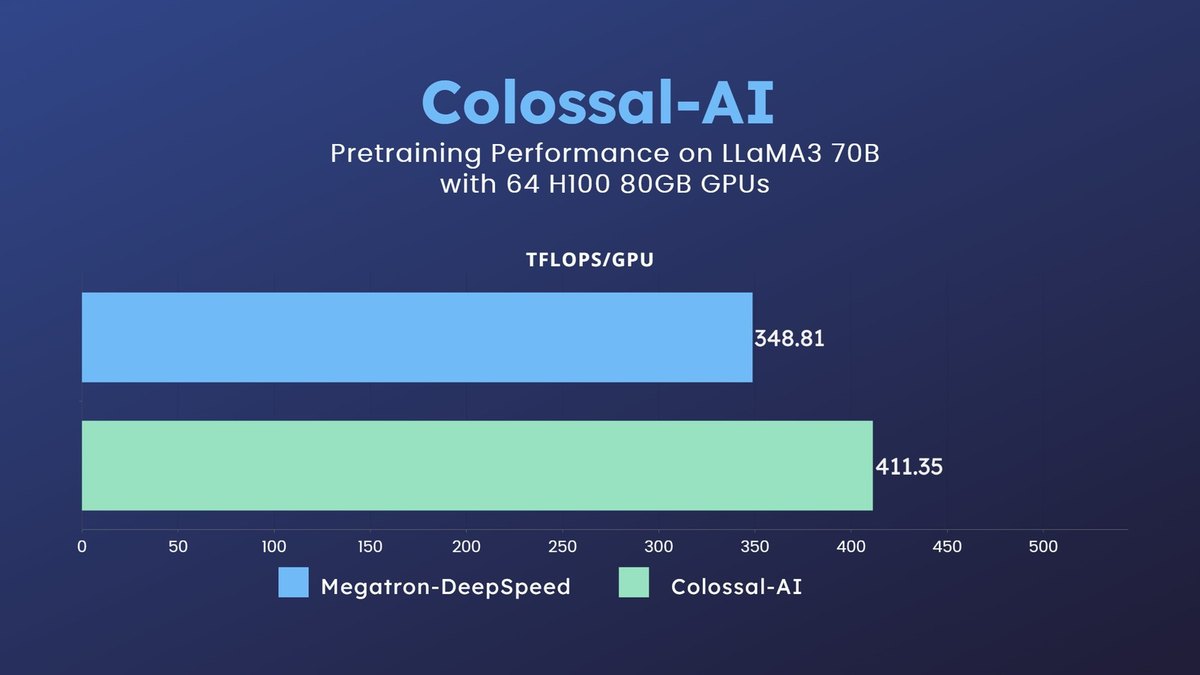
Colossal-AI offers data, pipeline, 1D, 2D, 2.5D and 3D tensor, and sequence parallelism. It is free under Apache-2.0 and has 41,431 GitHub stars as of Oct 20, 2026, but its latest release, v0.5.0, was published Jun 4, 2025.
MosaicML Composer
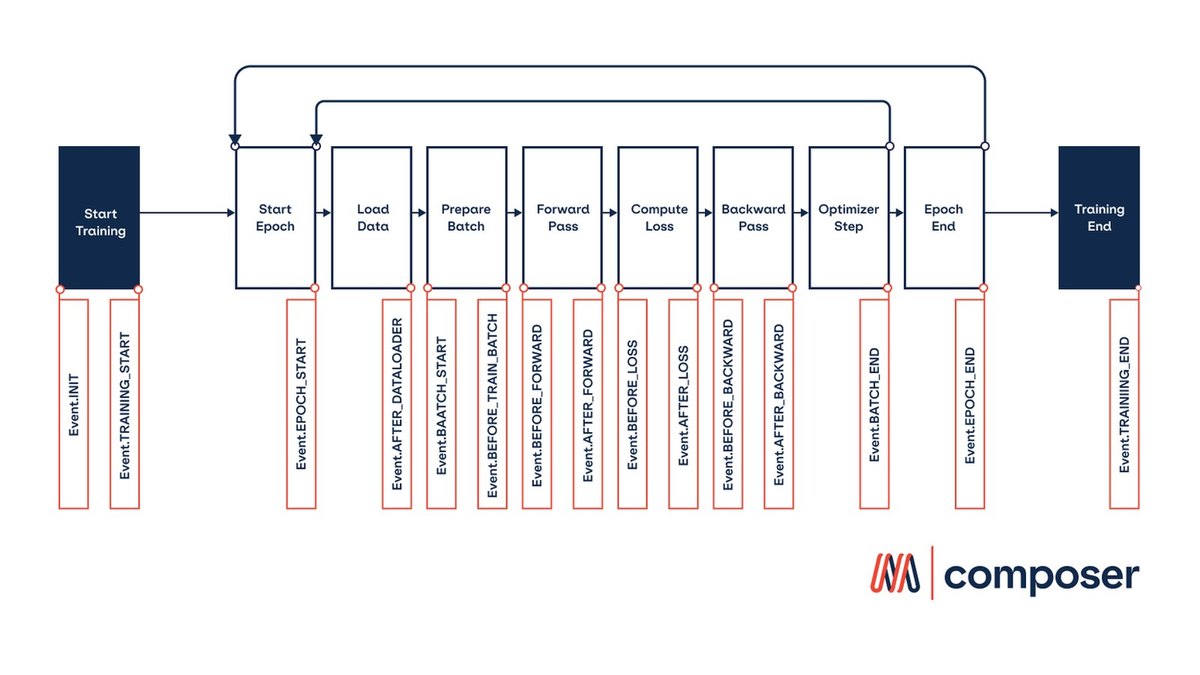
MosaicML Composer is an open-source library on top of PyTorch that makes distributed training workflows on large-scale clusters easier. Elastic sharded checkpointing lets you save on eight GPUs and resume on sixteen. It is free under Apache-2.0; the latest release is v0.32.1, published Jul 26, 2025.
Horovod
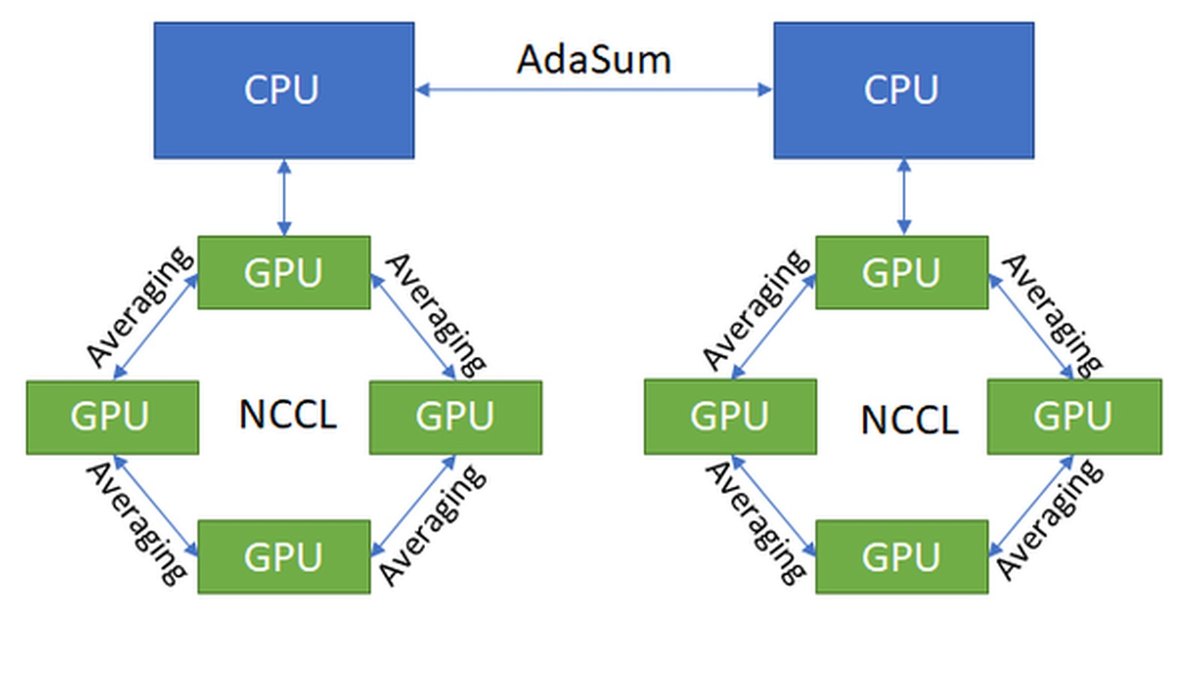
Horovod is distributed training for TensorFlow, Keras, PyTorch and Apache MXNet. Its README says that due to inactivity the project was archived in September 2026, and its latest release, v0.28.1, was published Jun 12, 2023. It is free under Apache-2.0 and has 14,678 GitHub stars as of Oct 20, 2026.
How we ranked these
Questions people ask
What is the best distributed training framework?
PyTorch FSDP is our #1 because sharding parameters, gradients and optimizer states is built into PyTorch itself; DeepSpeed is #2 and Megatron-LM is #3.
Are these frameworks free?
Yes. Every pick is open-source code on GitHub, and most state an Apache-2.0 license.
Is Horovod still maintained?
No. Its README says the project was archived in September 2026 due to inactivity, so it is #10 and best kept for existing jobs.
What is the easiest way to train on multiple GPUs?
Hugging Face Accelerate: its README says adding 5 lines to a standard PyTorch training script runs it on single or distributed setups.
GitHub stars on each project’s main repository, as of Oct 20, 2026 (PyTorch FSDP lives inside the PyTorch repo, so it is left out) at a glance
Official sites
- PyTorch FSDP · docs.pytorch.org
- DeepSpeed · github.com
- Megatron-LM · github.com
- Hugging Face Accelerate · github.com
- Ray Train · docs.ray.io
- PyTorch Lightning · github.com
- NVIDIA NeMo Automodel · github.com
- Colossal-AI · github.com
- MosaicML Composer · github.com
- Horovod · github.com
Sources
- github.com
- github.com
- github.com
- raw.githubusercontent.com
- github.com
- raw.githubusercontent.com
- github.com
- raw.githubusercontent.com
- github.com
- github.com
- github.com
- raw.githubusercontent.com
- raw.githubusercontent.com
- github.com
- github.com
- raw.githubusercontent.com
- github.com
- raw.githubusercontent.com
- github.com
- raw.githubusercontent.com
Prices, specs and availability change; confirm on the official site before you buy.