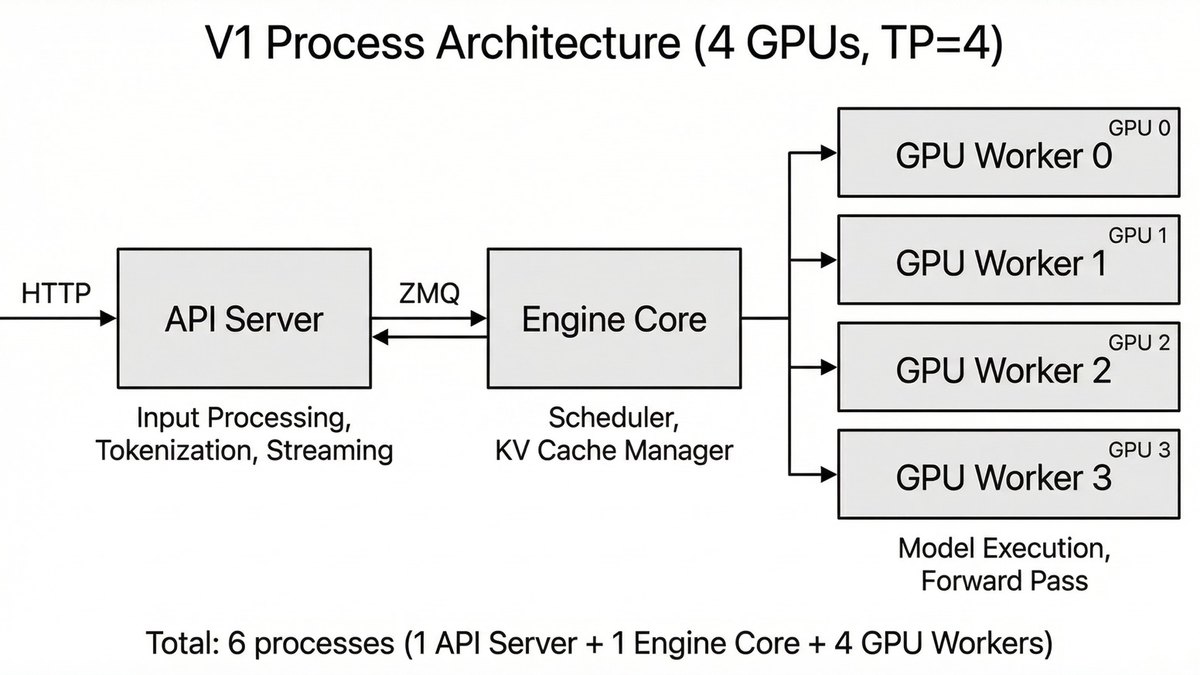
vLLM is the best model serving framework: a fast, open-source engine for LLM inference with an OpenAI-compatible API and support for 200+ model architectures. SGLang is #2 and TensorRT-LLM is #3. The ranking is based on what each framework does for serving models in production, then on how actively each project ships releases.
Price: Free; Apache-2.0 licenseWhat it does: Fast, easy-to-use library for LLM inference and serving, with PagedAttention, continuous batching, chunked prefill and prefix cachingAPI and models: OpenAI-compatible API server; supports 200+ model architectures on Hugging FaceGitHub stars: 96,529 (as of Nov 7, 2026)Latest release: v0.33.0rc3, published Nov 2, 2026
vLLM is a fast and easy-to-use library for LLM inference and serving, built on PagedAttention, continuous batching, chunked prefill and prefix caching. It offers an OpenAI-compatible API server and supports 200+ model architectures on Hugging Face. It is free under Apache-2.0, has 96,529 GitHub stars as of Nov 7, 2026, and its latest release is v0.33.0rc3, published Nov 2, 2026.
Go ifTeams that want one open engine for serving most Hugging Face LLMs on many kinds of hardware
Skip ifYou only serve small classic ML models
Why #1 over #2: It covers far more model architectures out of the box than TensorRT-LLM’s NVIDIA-only focus.
2
SGLang
Answrs VerdictThe strongest vLLM alternative for agentic serving.
Price: Free; Apache-2.0 licenseWhat it is: An open-source inference framework for large language, vision-language and diffusion models, optimized for agentic workloads, large-scale serving and RL rolloutsHardware: Supports NVIDIA, AMD and Intel hardware, Google TPUs and moreGitHub stars: 38,562 (as of Nov 7, 2026)Latest release: v0.5.23, published Nov 2, 2026
SGLang, hosted by the non-profit LMSYS, is an open-source inference framework for large language, vision-language and diffusion models, optimized for agentic workloads, large-scale serving and RL rollouts. It supports NVIDIA, AMD and Intel hardware and Google TPUs. It is free under Apache-2.0 and has 38,562 GitHub stars as of Nov 7, 2026; v0.5.23 was published Nov 2, 2026.
Go ifAgent and reasoning workloads that need a fast, actively developed engine
Skip ifYou want the largest community and model coverage
Why #2 over #3: It is built around agentic workloads, which suits them better than the general-purpose NVIDIA Dynamo-Triton.
3
TensorRT-LLM
Answrs VerdictNVIDIA’s own tuned engine for NVIDIA GPUs.
Price: Free; open-source library (its README license badge shows Apache 2)What it is: An open-sourced library for optimizing LLM and Visual Gen inference on NVIDIA GPUs, with custom kernels, prefill-decode disaggregation and speculative decodingAPI: A high-level Python LLM API for single-GPU to multi-node deployments, architected on PyTorchGitHub stars: 15,034 (as of Nov 7, 2026)Latest release: v1.2.1, published Apr 20, 2026
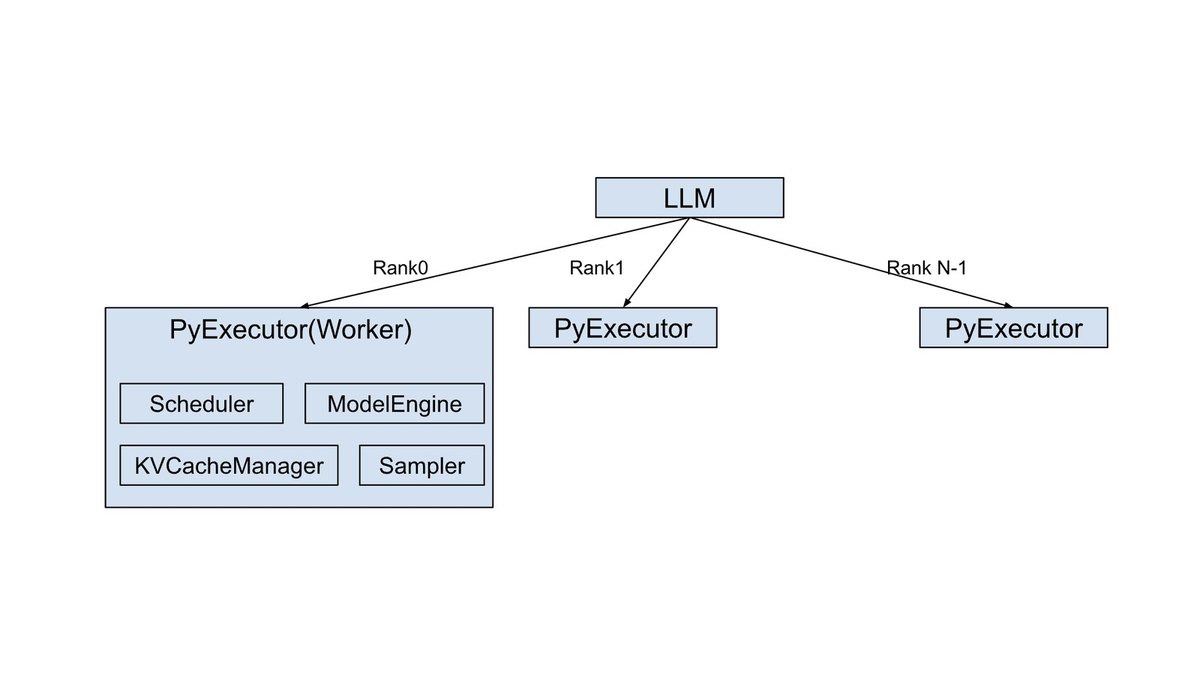
TensorRT-LLM, from NVIDIA, is an open-sourced library for optimizing LLM and Visual Gen inference on NVIDIA GPUs, with custom kernels, prefill-decode disaggregation and speculative decoding. It offers a high-level Python LLM API from single-GPU to multi-node deployments and has 15,034 GitHub stars as of Nov 7, 2026. Its latest release is v1.2.1, published Apr 20, 2026.
Go ifNVIDIA GPU fleets where the last bit of throughput matters
Skip ifYou run AMD, Intel or TPU hardware
Why #3 over #4: It is tuned specifically for NVIDIA GPUs, while Ray Serve is hardware-agnostic.
4
NVIDIA Dynamo-Triton
Answrs VerdictThe multi-framework server for mixed model fleets.
Price: Free and open source; also part of paid NVIDIA AI EnterpriseFormerly: NVIDIA Dynamo-Triton, formerly NVIDIA Triton Inference ServerFrameworks: Deploys models from TensorRT, PyTorch, ONNX, OpenVINO, Python and RAPIDS FIL, with dynamic batching and concurrent executionGitHub stars: 11,131 (as of Nov 7, 2026)Latest release: v2.74.0, published Nov 2, 2026
NVIDIA Dynamo-Triton, formerly NVIDIA Triton Inference Server, deploys models from TensorRT, PyTorch, ONNX, OpenVINO, Python and RAPIDS FIL with dynamic batching and concurrent execution. It is open source and is also part of NVIDIA AI Enterprise. The repository has 11,131 GitHub stars as of Nov 7, 2026; v2.74.0 was published Nov 2, 2026.
Go ifMixed fleets serving LLMs alongside vision, tabular and other model types
Skip ifYou only serve LLMs and want the simplest setup
Why #4 over #5: It serves many model frameworks, while Ray Serve asks you to wrap them in Python code.
5
Ray Serve
Answrs VerdictThe most flexible Python layer for multi-model services.
Price: Free; Apache-2.0 licenseWhat it is: A scalable, framework-agnostic model serving library for building online inference APIsLLM features: Response streaming, dynamic request batching and multi-node, multi-GPU servingComposition: Suited to model composition and multi-model serving in Python, with fractional GPUsLatest release: Ray 2.60.0, published Nov 4, 2026
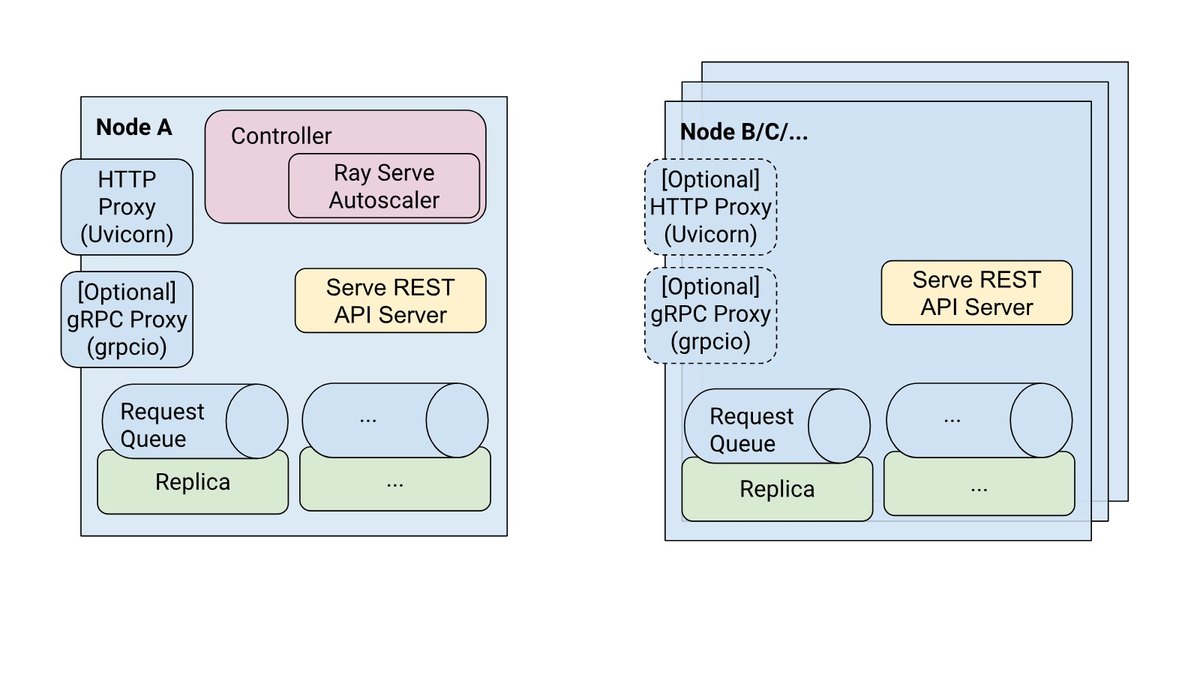
Ray Serve is a scalable, framework-agnostic model serving library for building online inference APIs. It offers response streaming, dynamic request batching, multi-node and multi-GPU serving, and fractional GPUs. It is well suited to composing several models and business logic in Python. It is free under Apache-2.0; Ray 2.60.0 was published Nov 4, 2026.
Go ifPython teams composing several models and business logic into one service
Skip ifYou only need a single-model LLM endpoint
Why #5 over #6: It composes multiple models in plain Python, which KServe does through Kubernetes configuration.
6
KServe
Answrs VerdictThe Kubernetes-native standard for serving both LLMs and classic models.
Price: Free; Apache-2.0 licenseWhat it is: A standardized distributed generative and predictive AI inference platform for scalable, multi-framework deployment on KubernetesLLM backends: Supports vLLM and llm-d, with an OpenAI-compatible inference protocolGovernance: A Cloud Native Computing Foundation (CNCF) incubating projectLatest release: v0.21.0, published Sep 25, 2026
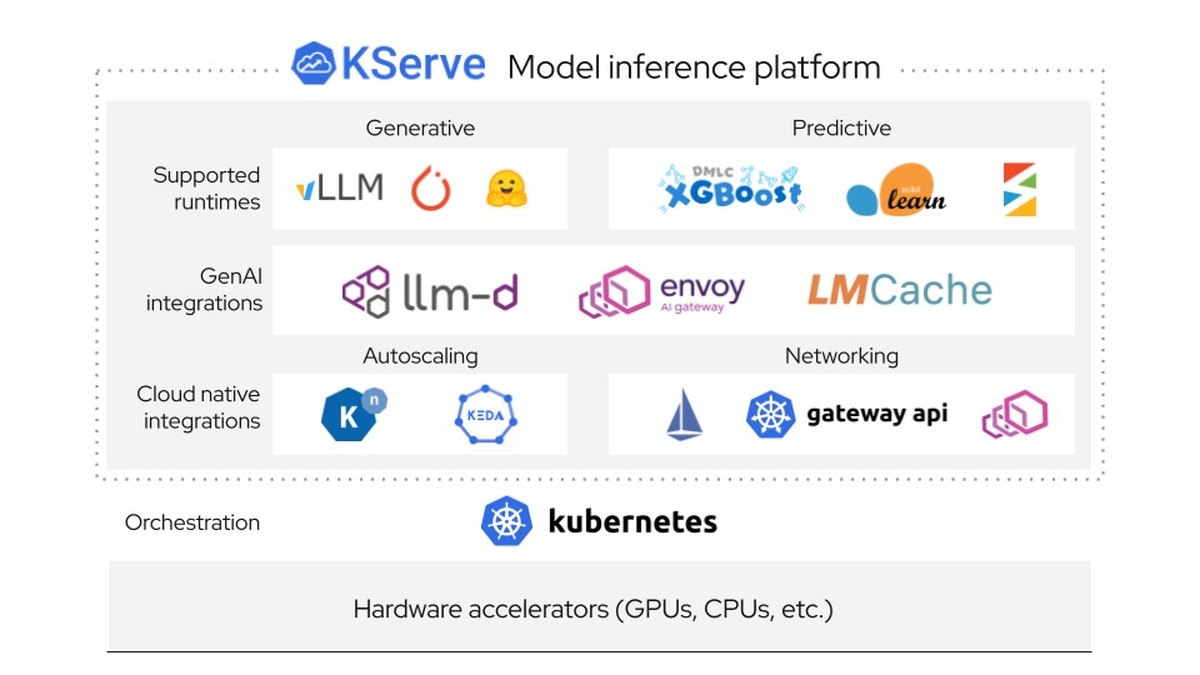
KServe is a standardized distributed generative and predictive AI inference platform for scalable, multi-framework deployment on Kubernetes. It supports vLLM and llm-d backends with an OpenAI-compatible inference protocol and is a Cloud Native Computing Foundation (CNCF) incubating project. It is free under Apache-2.0; v0.21.0 was published Sep 25, 2026.
Go ifPlatform teams that standardize model serving on Kubernetes
Skip ifYou do not run Kubernetes
Why #6 over #7: It is a full Kubernetes platform, whereas NVIDIA Dynamo focuses on routing and scaling LLM engines.
7
NVIDIA Dynamo
Answrs VerdictMulti-node orchestration on top of the engines above.
Price: Free; Apache-2.0 licenseWhat it is: An open-source, datacenter-scale inference stack: the orchestration layer above engines such as SGLang, TensorRT-LLM and vLLMFeatures: Disaggregated serving, KV-aware routing, multi-tier KV caching and automatic scalingGitHub stars: 8,453 (as of Nov 7, 2026)Latest release: v1.6.2, published Nov 5, 2026
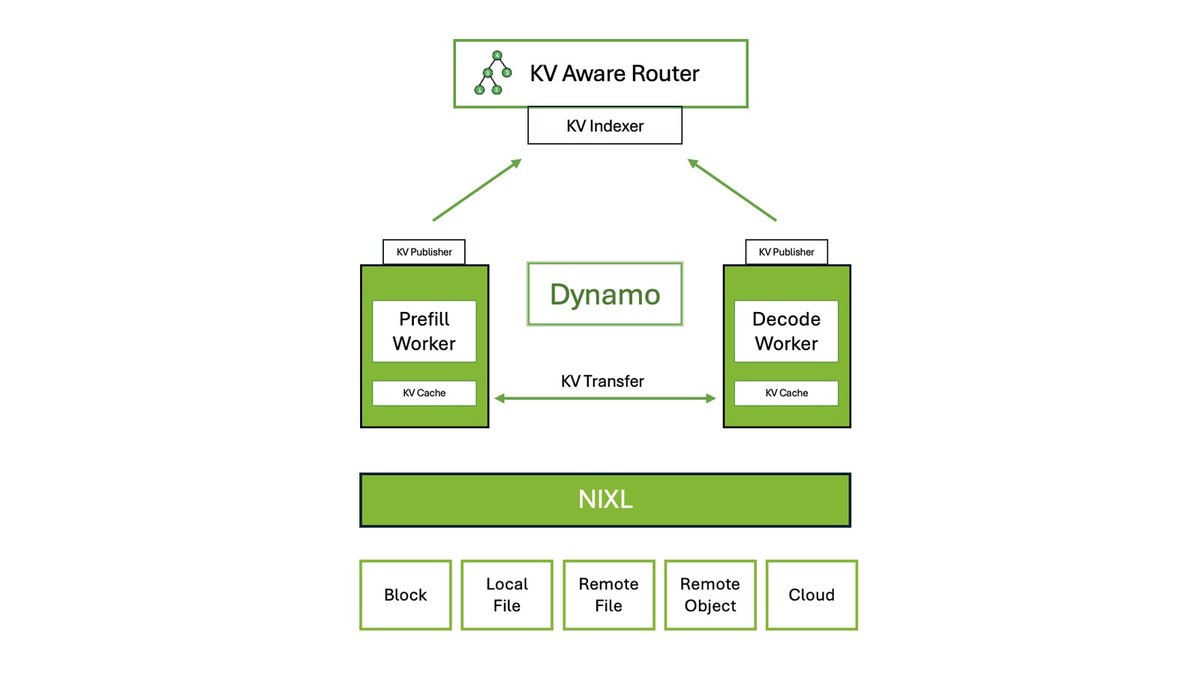
NVIDIA Dynamo is an open-source, datacenter-scale inference stack: the orchestration layer above engines such as SGLang, TensorRT-LLM and vLLM. It adds disaggregated serving, KV-aware routing, multi-tier KV caching and automatic scaling. It is free under Apache-2.0, has 8,453 GitHub stars as of Nov 7, 2026, and v1.6.2 was published Nov 5, 2026.
Go ifOperators running LLMs across many GPUs or nodes who need routing and scaling
Skip ifYou serve a single model on one machine
Why #7 over #8: It scales LLM engines across many nodes, which BentoML’s packaging approach does not.
8
BentoML
Answrs VerdictThe easiest packaging layer for custom model APIs.
Price: Free; Apache-2.0 licenseWhat it is: A Python library for building online serving systems for AI apps and model inferenceFeatures: Turns an inference script into a REST API, builds Docker images automatically, and offers dynamic batching and model parallelismGitHub stars: 8,934 (as of Nov 7, 2026)Latest release: v1.4.40, published Oct 23, 2026
BentoML is a Python library for building online serving systems for AI apps and model inference. It turns an inference script into a REST API, builds Docker images automatically, and offers dynamic batching and model parallelism. It is free under Apache-2.0, has 8,934 GitHub stars as of Nov 7, 2026, and v1.4.40 was published Oct 23, 2026.
Go ifDevelopers packaging any model as an API with Docker images and little ceremony
Skip ifYou need a purpose-built LLM engine with its own kernels
Why #8 over #9: It serves any model type, while llama.cpp is centered on its own model format and runtime.
9
llama.cpp
Answrs VerdictThe lightest way to serve models on modest hardware.
Price: Free; MIT licenseServer: Its HTTP server offers OpenAI-compatible chat completions and embeddings routes, continuous batching and parallel decoding with multi-user supportHardware: Runs F16 and quantized models on GPU and CPUGitHub stars: 133,667 (as of Nov 7, 2026)Latest release: v0.9.0, published Nov 4, 2026
llama.cpp includes an HTTP server with OpenAI-compatible chat completions and embeddings routes, continuous batching and parallel decoding with multi-user support. It runs F16 and quantized models on GPU and CPU. It is free under the MIT license and has 133,667 GitHub stars as of Nov 7, 2026; v0.9.0 was published Nov 4, 2026.
Go ifLocal, edge and CPU serving of quantized models
Skip ifYou need cluster-scale throughput on data-center GPUs
Why #9 over #10: It is actively released and recommended by Hugging Face’s own README, unlike Text Generation Inference.
10
Hugging Face Text Generation Inference
Answrs VerdictHistoric and in maintenance mode; keep it for existing deployments.
Price: Free; Apache-2.0 licenseStatus: Its README says TGI is now in maintenance mode, accepting only minor bug fixes, documentation and lightweight maintenanceRecommended instead: Its README recommends vLLM and SGLang, plus llama.cpp or MLX for local enginesGitHub stars: 10,881 (as of Nov 7, 2026)Latest release: v3.3.7, published Dec 19, 2025
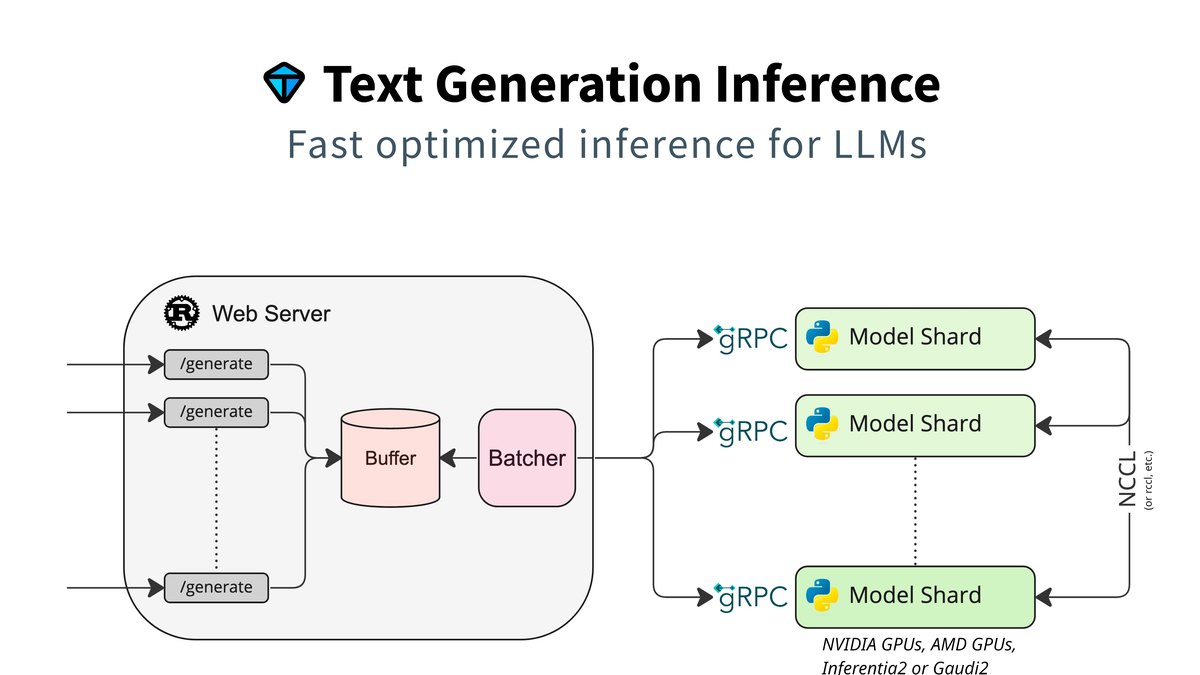
Hugging Face Text Generation Inference, or TGI, is a Rust, Python and gRPC server for text generation inference. Its README says it is now in maintenance mode, accepting only minor bug fixes, documentation improvements and lightweight maintenance, and recommends vLLM and SGLang going forward. Its latest release, v3.3.7, was published Dec 19, 2025, and it has 10,881 GitHub stars as of Nov 7, 2026.
Go ifMaintaining an existing TGI deployment
Skip ifYou are starting a new project
How we ranked these
We ranked the open-source frameworks on how much each does for serving models in production, using each project’s own README and docs, then on how actively each ships releases. Hugging Face Text Generation Inference comes last because its README says it is in maintenance mode. NVIDIA Dynamo-Triton and NVIDIA Dynamo are separate picks: the first is the multi-framework server formerly called Triton Inference Server, the second orchestrates LLM engines. All 10 picks are free open-source code; photos are official diagrams, logos and images from each project’s repository or site. GitHub star counts are as of Nov 7, 2026. Facts are taken from each maker's own published information; check the official site before you buy.
Questions people ask
What is the best model serving framework?
vLLM is our #1 because it is a fast, open-source serving engine with an OpenAI-compatible API and 200+ supported model architectures; SGLang is #2 and TensorRT-LLM is #3.
Are these model serving frameworks free?
Yes. Every pick is open-source code on GitHub; NVIDIA Dynamo-Triton is also sold as part of NVIDIA AI Enterprise.
Is Hugging Face Text Generation Inference still maintained?
Only lightly. Its README says TGI is in maintenance mode and recommends vLLM and SGLang going forward, so it is #10.
What happened to Triton Inference Server?
NVIDIA now calls it NVIDIA Dynamo-Triton, formerly NVIDIA Triton Inference Server; NVIDIA Dynamo is a separate project for LLM inference.
GitHub stars on each project’s main repository, as of Nov 7, 2026 (Ray Serve lives inside the Ray repository, so it is left out) at a glance
KServe6,199 stars
NVIDIA Dynamo8,453 stars
BentoML8,934 stars
Hugging Face Text Generation Inference10,881 stars
NVIDIA Dynamo-Triton11,131 stars
TensorRT-LLM15,034 stars
SGLang38,562 stars
vLLM96,529 stars
llama.cpp133,667 stars
GitHub stars on each project’s main repository, as of Nov 7, 2026 (Ray Serve lives inside the Ray repository, so it is left out), as published by each maker. Picks without a published figure are left off.