The 10 Best Embedding Models for Search and RAG in 2027
By Kory White · Updated Nov 2026 · 8 min read
Direct answer
Qwen3-Embedding-8B is the top embedding model for search and RAG in our scoring: on the MTEB leaderboard read on 2026-11-02 it has Mean (Task) 70.58 (rank 4 of 484) on Multilingual v2 and 75.22 (rank 5 of 350) on English v2, with an Apache 2.0 license and a 32k context. Google Gemini Embedding is #2 with a published price and a free tier, and Voyage 4 is #3 with the best retrieval ranking among hosted APIs. MTEB scores are largely self-reported and cover different tasks per model, so test candidates on your own data.
CC BY-NC 4.0 open weights, so commercial use needs a commercial license from Elastic; a per-million price is not stated on the pages read, and new users get free tokens
Teams that want a small, fast multilingual model with long context and Matryoshka truncation, and can license it commercially
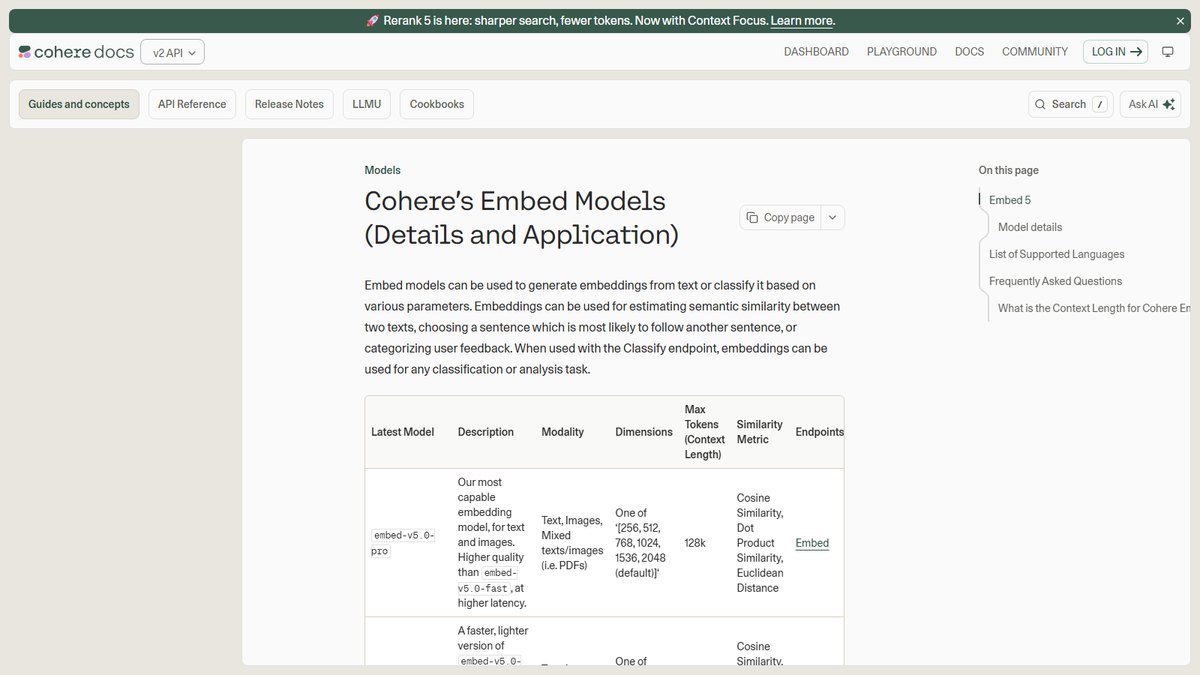
A per-token price for Embed v4 is not stated on the pages read; Embed 5 on Model Vault is $3.00/hour or $2,000/month for a Small instance and $5.00/hour or $3,250/month for Medium
Document-heavy RAG that needs a 128k context and mixed text and image inputs
Teams already on the OpenAI API that want a simple, well-documented default
Pick by what you want
Best overall
Qwen3-Embedding-8B
Best managed API with a free tier
Google Gemini Embedding
Best hosted retrieval ranking
Voyage 4
Best fully open (weights, code and data)
Nomic Embed Text v2
Best for long documents with images
Cohere Embed v4
The ranking
1
Qwen3-Embedding-8B
Answrs VerdictHighest leaderboard evidence on both multilingual and English MTEB among the models here, with a permissive license.
Price / license: Open weights under Apache 2.0; the model card lists no vendor priceMTEB Multilingual v2 (leaderboard): Mean (Task) 70.58, rank 4 of 484MTEB English v2 (leaderboard): Mean (Task) 75.22, rank 5 of 350RTEB retrieval (leaderboard): Rank 15 of 292 on RTEB(beta)Context and dimensions: 32k context and up to 4096 dimensions, with user-defined output sizes from 32 to 4096 (MRL support); supports 100+ languages including programming languages
Qwen3-Embedding-8B is open weights under Apache 2.0 from Alibaba’s Qwen team. On the MTEB leaderboard it has Mean (Task) 70.58, rank 4 of 484, on Multilingual v2 and 75.22, rank 5 of 350, on English v2, and sits at rank 15 of 292 on RTEB(beta). It has a 32k context, up to 4096 dimensions and user-defined output sizes from 32 to 4096, and supports 100+ languages including programming languages. The model card lists no vendor price.
Go ifTeams that want a top-ranked model they can self-host commercially under Apache 2.0, with adjustable vector size
Skip ifYou want a hosted API with a published per-token price
Why #1 over #2: It has higher MTEB means on both benchmarks and open weights, where Gemini Embedding is closed.
2
Google Gemini Embedding
Answrs VerdictStrong leaderboard results on both text benchmarks plus a published price and multimodal input.
Price / license: gemini-embedding-001 is $0.15 per 1M tokens paid ($0.075 batch); gemini-embedding-2 is $0.20 per 1M tokens ($0.10 batch); both have a free tierMTEB Multilingual v2 (leaderboard): gemini-embedding-001 Mean (Task) 68.37, rank 5 of 484MTEB English v2 (leaderboard): gemini-embedding-001 Mean (Task) 73.3, rank 9 of 350RTEB retrieval (leaderboard): gemini-embedding-001 rank 13 of 292 on RTEB(beta)Context and dimensions: 001 takes 2,048 input tokens and gemini-embedding-2 takes 8,192; both output 128 to 3072 dimensions (default 3072) with Matryoshka via output_dimensionality; gemini-embedding-2 takes text, image, video, audio and PDF and lists over 100 languages
Gemini Embedding is Google’s managed API. gemini-embedding-001 has Mean (Task) 68.37, rank 5 of 484, on Multilingual v2, 73.3, rank 9 of 350, on English v2 and rank 13 of 292 on RTEB(beta). It costs $0.15 per 1M tokens paid ($0.075 batch), and gemini-embedding-2 costs $0.20 per 1M tokens ($0.10 batch), both with a free tier. Both output 128 to 3072 dimensions with Matryoshka; gemini-embedding-2 takes 8,192 tokens and accepts text, image, video, audio and PDF, while 001 takes 2,048 tokens and is text only.
Go ifTeams already on Google Cloud or AI Studio that want a managed API with a free tier and adjustable dimensions
Skip ifYou need weights you can run yourself
Why #2 over #3: It has full MTEB means on both benchmarks, where Voyage 4 shows only a retrieval rank.
3
Voyage 4
Answrs VerdictBest independent retrieval ranking among the hosted APIs here, with a clear price ladder.
Price / license: voyage-4-large $0.12 per 1M tokens, voyage-4 $0.06 and voyage-4-lite $0.02, with the first 200 million tokens freeRTEB retrieval (leaderboard): voyage-4-large rank 6 of 292 on RTEB(beta); no full MTEB Multilingual v2 or English v2 score is shownContext and dimensions: 32,000-token context; 2048, 1024 (default), 512 and 256 dimensions via Matryoshka; float, int8, uint8 and binary output typesShared space (vendor-stated): All four voyage-4 models (large, standard, lite and nano) produce compatible embeddings, so you can embed documents with one and queries with anotherVendor benchmark (vendor-stated): Voyage says voyage-4-large leads Gemini Embedding 001 by 3.87%, Cohere Embed v4 by 8.20% and OpenAI v3 Large by 14.05% on average across 29 RTEB datasets in its own evaluation; voyage-4-nano is open-weight under Apache 2.0
Voyage 4 is a family from Voyage AI, now part of MongoDB. voyage-4-large ranks 6 of 292 on RTEB(beta), the best retrieval rank among the hosted APIs here, but no full MTEB Multilingual v2 or English v2 score is shown. It has a 32,000-token context, Matryoshka sizes of 2048, 1024 (default), 512 and 256, and quantized outputs. Prices are $0.12, $0.06 and $0.02 per 1M tokens for large, standard and lite, with the first 200 million tokens free. Voyage says all four models are compatible, and its lead claims over Gemini, Cohere and OpenAI are vendor-stated.
Go ifRAG teams that want the best retrieval-focused ranking and cheap tiers they can mix in one index
Skip ifYou need a full multilingual MTEB score or open weights for the main models
Why #3 over #4: It has the strongest retrieval rank and the most detailed price ladder, where Jina’s weights carry a non-commercial license.
4
Jina Embeddings v5
Answrs VerdictHigh leaderboard rank for a sub-1B model, held back by its non-commercial license.
Price / license: CC BY-NC 4.0 open weights, so commercial use needs a commercial license from Elastic; a per-million price is not stated on the pages read, and new users get free tokensMTEB Multilingual v2 (leaderboard): v5-omni-small Mean (Task) 67.0, rank 14 of 484MTEB English v2 (leaderboard): v5-omni-small Mean (Task) 71.78, rank 14 of 350RTEB retrieval (leaderboard): v5-text-small rank 26 of 292 on RTEB(beta)Context and dimensions: v5-text-small has 677M parameters, a 32768-token context, 1024 dimensions and Matryoshka sizes from 32 to 1024; Jina states 119+ languages and 71.7 on MTEB English v2 (vendor-stated)
Jina Embeddings v5 has a 32768-token context, 1024 dimensions and Matryoshka sizes from 32 to 1024 on v5-text-small (677M parameters). The leaderboard shows v5-omni-small at Mean (Task) 67.0, rank 14 of 484, on Multilingual v2 and 71.78, rank 14 of 350, on English v2, and v5-text-small at rank 26 of 292 on RTEB(beta). Jina states 119+ languages. The weights are CC BY-NC 4.0, so commercial use needs a commercial license from Elastic, and no per-million price was stated on the pages read.
Go ifTeams that want a small, fast multilingual model with long context and Matryoshka truncation, and can license it commercially
Skip ifYou need a permissive open license with no extra agreement
Why #4 over #5: It has full MTEB means and long context, where Snowflake Arctic Embed 2.0 sits much lower on the leaderboard.
5
Snowflake Arctic Embed 2.0
Answrs VerdictPermissive and compression-friendly, but mid-table on independent benchmarks.
Price / license: Open weights under Apache 2.0; the model card lists no vendor priceMTEB Multilingual v2 (leaderboard): arctic-embed-l-v2.0 Mean (Task) 57.03, rank 64 of 484MTEB English v2 (leaderboard): arctic-embed-l-v2.0 Mean (Task) 63.6, rank 103 of 350RTEB retrieval (leaderboard): Rank 47 of 292 on RTEB(beta)Context and compression (vendor-stated): 8192-token context and 1024 dimensions; Snowflake reports average NDCG@10 of 55.6 on BEIR, 55.8 on MIRACL and 54.3 on CLEF (Full), and says Matryoshka truncation to 256 dimensions cuts vector size 4x with less than 3% quality loss
Snowflake Arctic Embed 2.0 is open weights under Apache 2.0 with an 8192-token context and 1024 dimensions. The leaderboard shows Mean (Task) 57.03, rank 64 of 484, on Multilingual v2, 63.6, rank 103 of 350, on English v2 and rank 47 of 292 on RTEB(beta). Snowflake reports average NDCG@10 of 55.6 on BEIR, 55.8 on MIRACL and 54.3 on CLEF (Full), and says Matryoshka truncation to 256 dimensions cuts vector size 4x with less than 3% quality loss, all vendor-stated.
Go ifCost-conscious teams that want compact vectors, an Apache 2.0 license and multilingual retrieval
Skip ifYou want top-tier leaderboard scores
Why #5 over #6: It documents Matryoshka compression with a quality figure and has a better RTEB rank, where BGE-M3 does not mention Matryoshka.
6
BGE-M3
Answrs VerdictA flexible, permissively licensed workhorse that has aged on newer benchmarks.
Price / license: Open weights under the MIT license; the model card lists no vendor priceMTEB Multilingual v2 (leaderboard): Rank 52 of 484; no Mean (Task) is shown because not every task has a resultRTEB retrieval (leaderboard): Rank 52 of 292 on RTEB(beta)Context and dimensions: 8192-token context and 1024 dimensions; the model card does not mention MatryoshkaRetrieval modes: Does dense, multi-vector and sparse retrieval in one model and supports more than 100 working languages
BGE-M3 from BAAI is open weights under the MIT license with an 8192-token context and 1024 dimensions. It does dense, multi-vector and sparse retrieval in one model and supports more than 100 working languages. On the leaderboard it ranks 52 of 484 on Multilingual v2 with no mean shown and 52 of 292 on RTEB(beta). The model card does not mention Matryoshka, and lists no vendor price.
Go ifHybrid search setups that want dense and sparse signals from one MIT-licensed model
Skip ifYou need adjustable vector sizes
Why #6 over #7: It has a longer context and a broader license position than Nomic Embed Text v2, which is capped at 512 tokens.
7
Nomic Embed Text v2
Answrs VerdictThe most open pick here, limited by a short 512-token window.
Price / license: Open weights under Apache 2.0; weights, code and training data are releasedMTEB Multilingual v2 (leaderboard): nomic-embed-text-v2-moe Mean (Task) 57.64, rank 57 of 484MTEB English v2 (leaderboard): Mean (Task) 63.64, rank 102 of 350RTEB retrieval (leaderboard): Mean (Task) 46.14, rank 44 of 292 on RTEB(beta)Context and dimensions: 512-token maximum, Matryoshka sizes from 768 down to 256, 475M total and 305M active parameters (Mixture of Experts with 8 experts, top-2 routing); about 100 languages, trained on over 1.6B pairs; Nomic reports 52.86 on BEIR and 65.80 on MIRACL (vendor-stated)
Nomic Embed Text v2 is open weights under Apache 2.0, with weights, code and training data released. It has 475M total and 305M active parameters in a Mixture of Experts design, a 512-token maximum, Matryoshka sizes from 768 down to 256 and about 100 languages. The leaderboard shows Mean (Task) 57.64, rank 57 of 484, on Multilingual v2, 63.64, rank 102 of 350, on English v2, and 46.14, rank 44 of 292, on RTEB(beta). Nomic reports 52.86 on BEIR and 65.80 on MIRACL, vendor-stated.
Go ifTeams that value fully open training data and code and only embed short passages
Skip ifYou embed long documents without chunking
Why #7 over #8: It is fully open and commercially usable, where NVIDIA’s model is restricted to non-commercial use.
8
NVIDIA Llama-Embed-Nemotron-8B
Answrs VerdictTop-three multilingual score and the most transparent recipe, but restricted to non-commercial use.
Price / license: NVIDIA license with Llama 3.1 community terms; the card says the model is for non-commercial and research use onlyMTEB Multilingual v2 (leaderboard): Mean (Task) 69.46, rank 3 of 484RTEB retrieval (leaderboard): Rank 232 of 292 on RTEB(beta)Context and dimensions: 4096 dimensions and a 32768-token context per the leaderboard entry; the card does not mention MatryoshkaTransparency: NVIDIA releases the weights, a technical report, the training dataset and the full training code
NVIDIA Llama-Embed-Nemotron-8B has Mean (Task) 69.46, rank 3 of 484, on MTEB Multilingual v2, but rank 232 of 292 on RTEB(beta). It has 4096 dimensions and a 32768-token context per the leaderboard entry. NVIDIA releases the weights, a technical report, the training dataset and the full training code. The license is the NVIDIA license with Llama 3.1 community terms, and the card says it is for non-commercial and research use only.
Go ifResearch teams that want a near-top multilingual score with a fully documented training recipe
Skip ifYou plan commercial use
Why #8 over #9: It has a full multilingual score and a fully documented recipe, where Cohere Embed v4 shows no mean on any MTEB set.
9
Cohere Embed v4
Answrs VerdictLong context and multimodal input, but thin independent evidence and no published per-token price.
Price / license: A per-token price for Embed v4 is not stated on the pages read; Embed 5 on Model Vault is $3.00/hour or $2,000/month for a Small instance and $5.00/hour or $3,250/month for MediumRTEB retrieval (leaderboard): Embed v4 rank 36 of 292 on RTEB(beta); rank 466 of 484 on MTEB Multilingual v2 with no mean shownContext and dimensions: embed-v4.0 has a 128k context and dimensions of 256, 512, 1024 and 1536 (default), for text, images and mixed PDFsEmbed 5: Cohere also lists embed-v5.0-pro and embed-v5.0-fast with a 128k context, Matryoshka sizes from 256 to 2048 and 100+ languages; no Embed 5 entry appears in the leaderboard model list read
Cohere Embed v4 has a 128k context and dimensions of 256, 512, 1024 and 1536 (default), for text, images and mixed PDFs. The leaderboard shows it at rank 36 of 292 on RTEB(beta) and rank 466 of 484 on Multilingual v2 with no mean shown. A per-token price was not stated on the pages read; Embed 5 on Model Vault is $3.00/hour or $2,000/month for a Small instance and $5.00/hour or $3,250/month for Medium. Cohere also lists embed-v5.0-pro and embed-v5.0-fast, which do not appear in the leaderboard model list read.
Go ifDocument-heavy RAG that needs a 128k context and mixed text and image inputs
Skip ifYou need independent benchmark scores for the newest Embed 5 models
Why #9 over #10: It has a much longer context and image input, where OpenAI’s model takes 8192 tokens of text.
10
OpenAI text-embedding-3-large
Answrs VerdictA convenient default with a published price, but newer models rank well above it on the leaderboard.
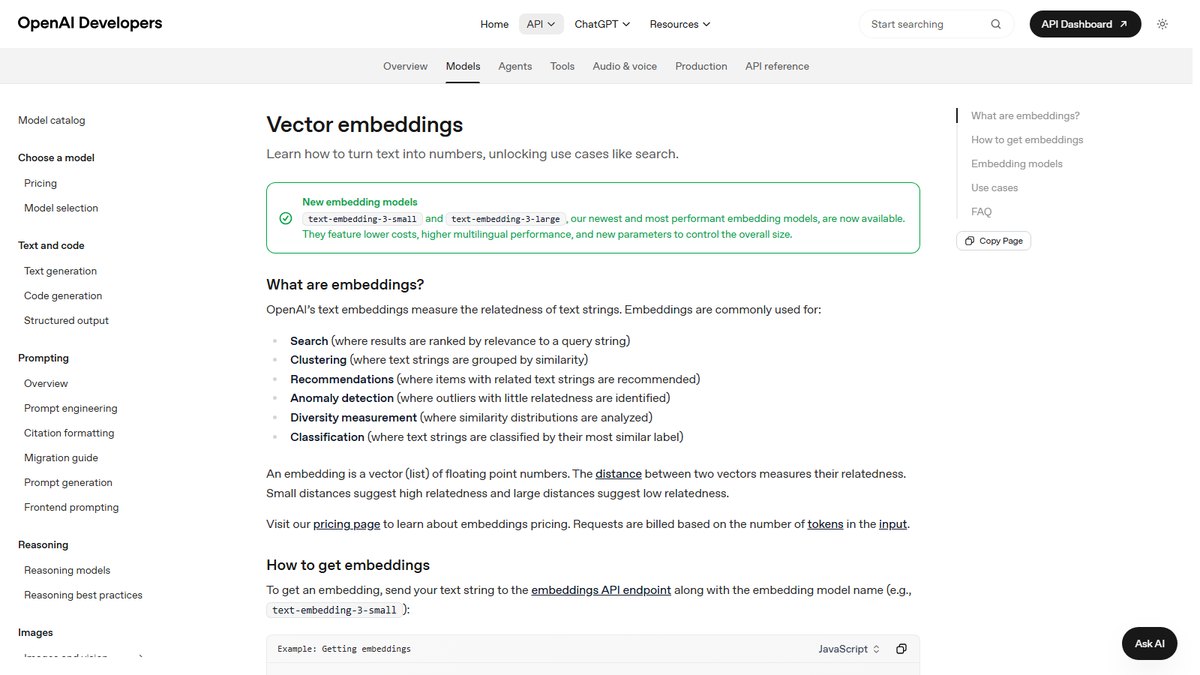
Price / license: $0.13 per 1M tokens, closed modelRTEB retrieval (leaderboard): Rank 39 of 292 on RTEB(beta); rank 45 of 484 on MTEB Multilingual v2 and 90 of 350 on English v2, with no mean shownContext and dimensions: 8192 max input tokens and 3072 default dimensions; the dimensions parameter shortens embeddingsMTEB (vendor-stated): OpenAI lists 64.6% on its MTEB eval for text-embedding-3-large
OpenAI text-embedding-3-large costs $0.13 per 1M tokens and takes 8192 max input tokens with 3072 default dimensions; the dimensions parameter shortens embeddings. OpenAI lists 64.6% on its own MTEB eval, vendor-stated. On the leaderboard it ranks 39 of 292 on RTEB(beta), 45 of 484 on Multilingual v2 and 90 of 350 on English v2, with no mean shown. It is closed and lists no language count.
Go ifTeams already on the OpenAI API that want a simple, well-documented default
Skip ifYou want leaderboard-leading retrieval quality or a stated language list
Related: where to store the vectors
Embeddings need a place to live and be searched. For the vector databases that sit behind these models, see our companion ranking.
This list is about embedding models for search and RAG. Each pick was scored out of 100 with the same rubric and evidence standard: independent benchmark evidence from the MTEB leaderboard, read directly on 2026-11-02 (30 points), price or open license (20), context length, dimensions and Matryoshka support as documented (20), multilingual coverage (15) and transparency (15). Scores: Qwen3-Embedding-8B ninety-four, Google Gemini Embedding eighty-one, Voyage 4 eighty, Jina Embeddings v5 seventy-seven, Snowflake Arctic Embed 2.0 seventy-four, BGE-M3 and Nomic Embed Text v2 seventy-three each (BGE-M3 first on benchmark points), NVIDIA Llama-Embed-Nemotron-8B sixty-nine, Cohere Embed v4 sixty, OpenAI text-embedding-3-large fifty-four. The weights and scores are our judgment from the pages read, not vendor data, and no company paid for or adjusted a position. MTEB has caveats: most results are submitted by the model makers, models are evaluated on different task subsets, so a rank can appear without a Mean (Task), and public test sets can leak into training data. We therefore read both the Multilingual v2 and English v2 benchmarks and the RTEB retrieval benchmark, and label every vendor figure as vendor-stated. Where a model had no leaderboard mean we say so rather than fill the gap. Prices are those published on each maker’s pages; the open models have no vendor price. Facts are taken from each maker's own published information; check the official site before you buy.
Questions people ask
What is the best embedding model for search and RAG?
Qwen3-Embedding-8B scores highest in our rubric: it has the best leaderboard results among the models here (Mean (Task) 70.58, rank 4 of 484 on MTEB Multilingual v2 and 75.22, rank 5 of 350 on English v2), an Apache 2.0 license, a 32k context and adjustable output sizes from 32 to 4096. Google Gemini Embedding is #2 and Voyage 4 is #3.
Is MTEB a reliable way to pick an embedding model?
It is a useful starting point, not proof. Models appear on the leaderboard with different task coverage, so some entries show a rank but no Mean (Task), and ranks are not comparable across such entries. Most scores are also self-reported by the model makers. Test two or three candidates on your own documents and queries before committing.
Which embedding models are cheapest or free?
Qwen3-Embedding-8B (Apache 2.0), Snowflake Arctic Embed 2.0 (Apache 2.0), BGE-M3 (MIT) and Nomic Embed Text v2 (Apache 2.0) are open weights you can run yourself. Among hosted APIs, Voyage lists $0.02 per 1M tokens for voyage-4-lite with the first 200 million tokens free, and Google has a free tier.
Which models support Matryoshka (shortened) vectors?
Qwen3-Embedding-8B, Gemini Embedding, Voyage 4, Jina Embeddings v5, Snowflake Arctic Embed 2.0, Nomic Embed Text v2 and Cohere Embed 5 document adjustable output sizes. OpenAI offers a dimensions parameter that shortens embeddings. BGE-M3 and NVIDIA Llama-Embed-Nemotron-8B cards do not mention it.
MTEB Multilingual v2 Mean (Task) on the leaderboard, read 2026-11-02 (points) at a glance
Snowflake Arctic Embed 2.057.03 points
Nomic Embed Text v257.64 points
Jina Embeddings v5 (omni-small)67 points
Google Gemini Embedding (001)68.37 points
NVIDIA Llama-Embed-Nemotron-8B69.46 points
Qwen3-Embedding-8B70.58 points
MTEB Multilingual v2 Mean (Task) on the leaderboard, read 2026-11-02 (points), as published by each maker. Picks without a published figure are left off.